Site Reliability Engineer
GPU fleet reliability and the observability stack that keeps NVIDIA HGX clusters running. The CI/CD pipelines, Kubernetes autoscalers, and Terraform infrastructure built to self-heal under pressure.
The hard problems:
- Ensuring reliable training on supercomputer clusters, bridging both low-level hardware domain and the training code to work in concert on thousands of nodes and tens of thousands of GPUs.
- Profiling GPU performance at kernel level across CUDA, ROCm, and InfiniBand to decide whether hardware meets production bar before it ships.
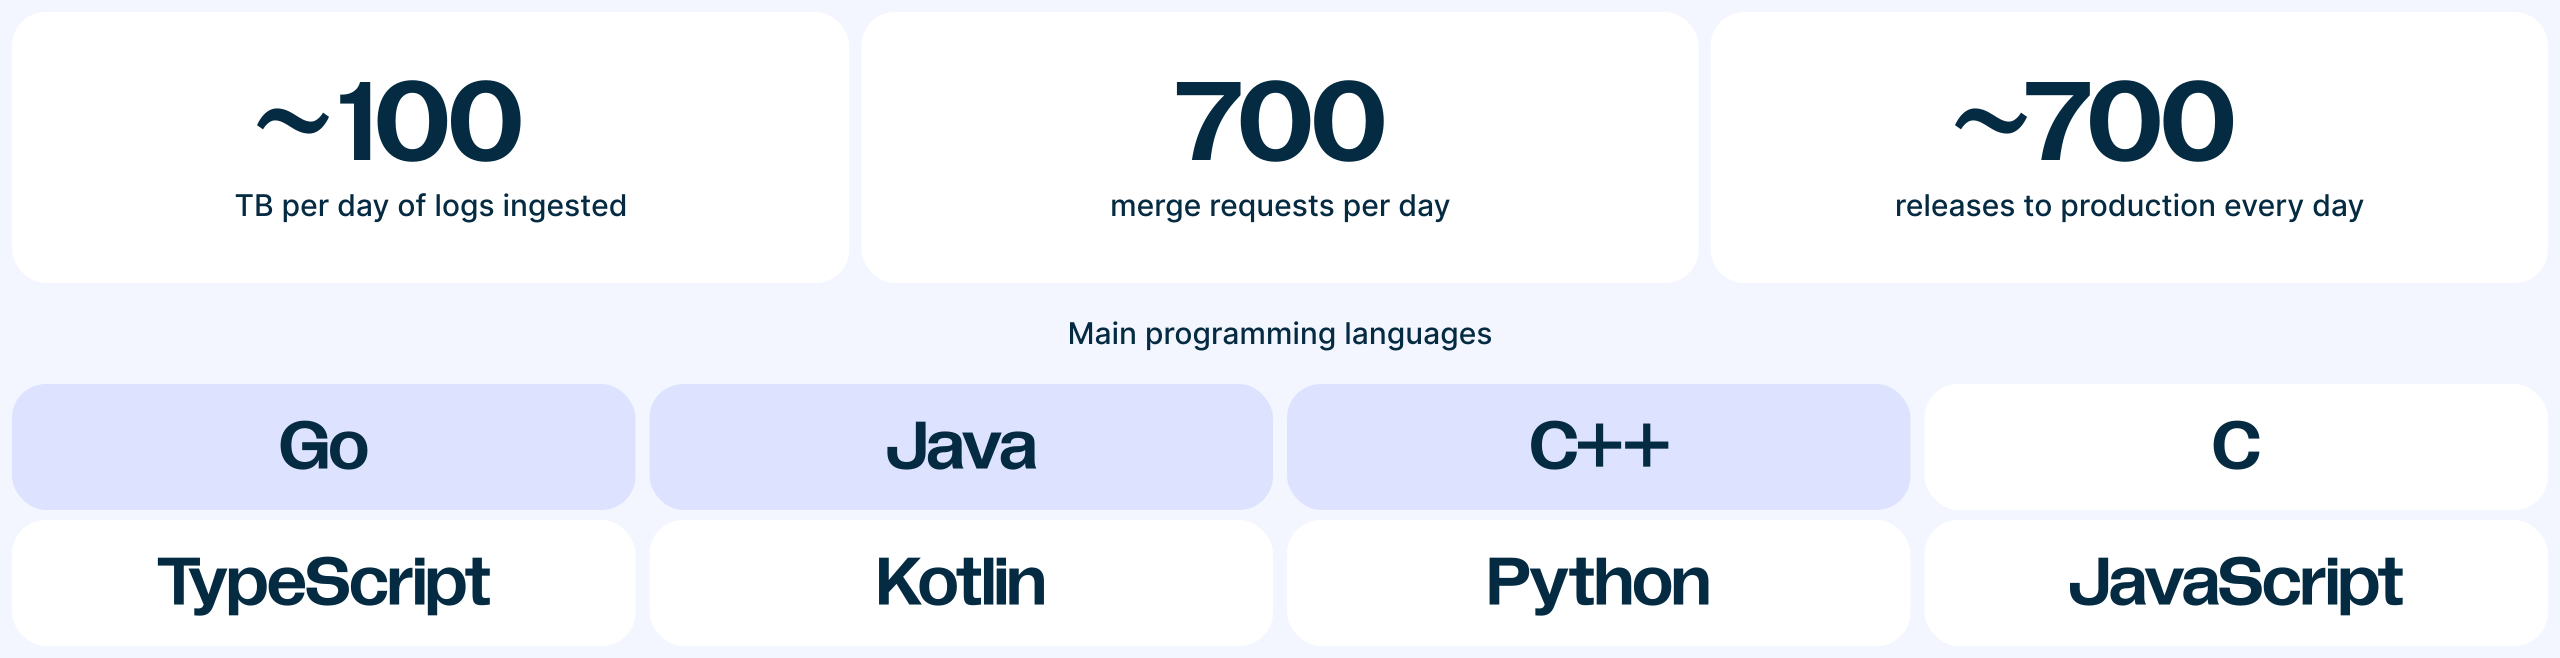
- Running 25,000 CI builds a day on a monorepo at FAANG scale, without making engineers wait.
- Designing telemetry pipelines that turn hundreds of terabytes of signal into a clear answer about what went wrong, not just that it did.
- Developing Kubernetes operators for training, solving non-trivial autoscaling problems for inference, all working on scale of thousands.
- Building the runbooks and automation that catch incidents before they become outages.