
MLPerf® Training v6.1: Nebius ranks 1st on NVIDIA Vera Rubin at rack scale in pre-training and post-training
MLPerf® Training v6.1: Nebius ranks 1st on NVIDIA Vera Rubin at rack scale in pre-training and post-training
Today we’re announcing our latest submission to MLPerf® Training v6.1, the industry-standard benchmark for AI training performance developed by MLCommons®. This round marks a generational step for Nebius: our first MLPerf® Training results on the NVIDIA Vera Rubin platform. In this blog we’re also sharing updated MLPerf® Inference v6.1 results, now measured on an Available NVIDIA Vera Rubin NVL72 system*.
In this round, we submitted results on two NVIDIA platforms: NVIDIA Vera Rubin NVL72 and NVIDIA GB300 NVL72. Each ran as a 16-node cluster with 64 GPUs. We benchmarked two workloads: gpt-oss 20B pre-training and Qwen3.5-397B post-training with GRPO, a reinforcement learning workload introduced in this round.
Three results stand out:
- On NVIDIA Vera Rubin NVL72, our 64-GPU system delivered the fastest gpt-oss 20B and Qwen3.5-397B results among Vera Rubin NVL72 submissions up to full-rack scale.
- NVIDIA Vera Rubin NVL72 cuts model training time by 39% on gpt-oss 20B and by 33% on Qwen3.5-397B compared to NVIDIA GB300 NVL72 at the same scale.
- NVIDIA GB300 NVL72, which we previously benchmarked on bare metal, now runs on our virtual cloud platform and demonstrated the fastest 64-GPU GB300 result on gpt-oss 20B in the Available cloud category.
Below is the table with all four results:
Time-to-train in minutes; lower values indicate better performance. Positions are among Closed division submissions with the same GPU type at 64 GPUs.
Our First MLPerf® Training results on NVIDIA Vera Rubin NVL72
Our NVIDIA Vera Rubin NVL72 system paired 64 NVIDIA Rubin GPUs with 32 NVIDIA Vera CPUs.
The fastest pre-training result on 64 NVIDIA Rubin GPUs
A Vera Rubin NVL72 rack holds 18 compute nodes with four GPUs each. We run customer clusters on 16 of them and keep two as hot spares, so a node failure doesn’t shrink the cluster. We benchmarked exactly that 16-node setup and it still outperformed full 72-GPU racks [6].
Even with 64 of the rack’s 72 GPUs, our system delivered the fastest gpt-oss 20B result among all single-rack Vera Rubin NVL72 submissions: 11.21 minutes [1]. That is about 10% faster than the next-fastest result at that scale [5].
The fastest reinforcement learning results with Qwen3.5-397B on 64 NVIDIA Rubin GPUs
The Qwen3.5-397B GRPO benchmark joins the MLPerf® Training suite in this round. It post-trains a 397B-parameter mixture-of-experts model with GRPO, a reinforcement learning method, on software engineering tasks. Each run alternates between generating candidate solutions and updating the model, so the system has to handle generation and training in the same job.
On this workload, our Vera Rubin NVL72 system reached the quality target in 24.82 minutes [2]. This is the fastest 64-GPU Vera Rubin NVL72 result, about 4.5% faster than the next one [7].
Performance improvements from NVIDIA Blackwell Ultra to NVIDIA Vera Rubin
Both of our systems ran as 16-node clusters with 64 GPUs on the same two workloads. This gives a like-for-like view of the generational step from NVIDIA Blackwell Ultra to NVIDIA Rubin on our own infrastructure.
At matched scale, Vera Rubin NVL72 trained gpt-oss 20B 1.63x faster than GB300 NVL72, cutting time-to-train by 39%. On Qwen3.5-397B GRPO, it was 1.49x faster, a 33% reduction [1][2][3][4].
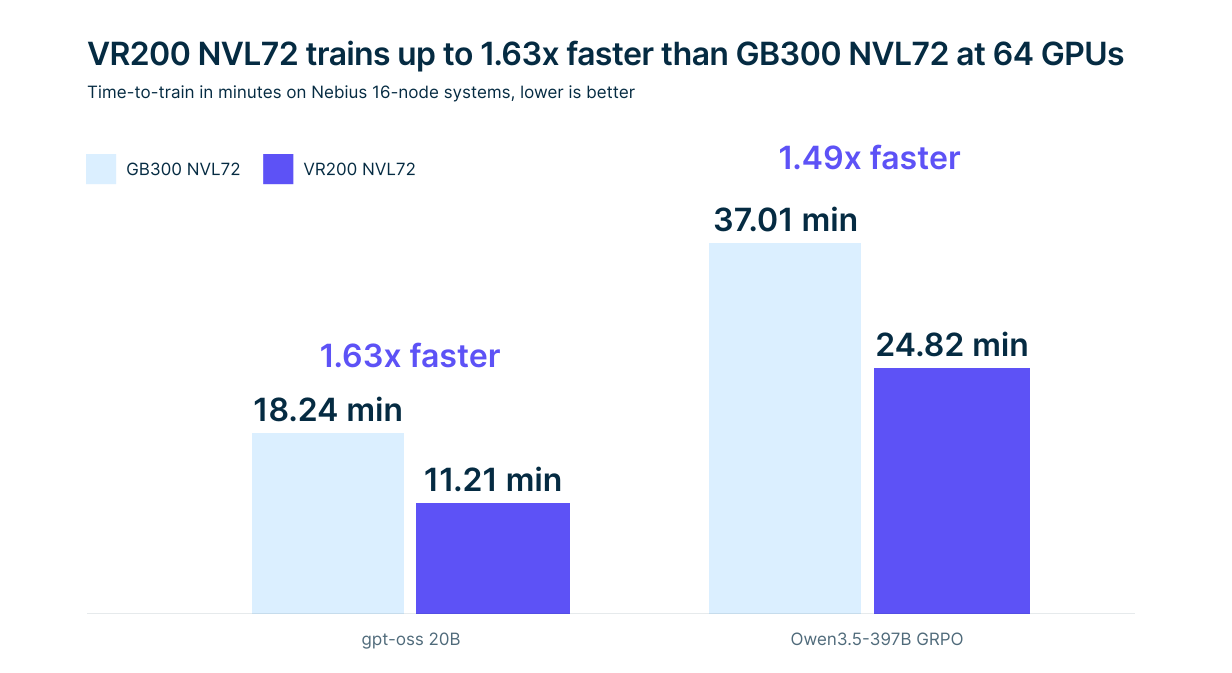
The performance improvements are visible across the whole round. On gpt-oss 20B, only GB300 systems with 512 GPUs trained faster than our 64-GPU Vera Rubin NVL72 system [1].
We ran our GB300 NVL72 system on Nebius AI Cloud. It paired 64 NVIDIA Blackwell Ultra GPUs with 32 NVIDIA Grace CPUs. With 64 GPUs, it trained gpt-oss 20B in 18.24 minutes, the fastest 64-GPU GB300 result in this round in the Available cloud category and nearly identical to the 72-GPU time of 18.20 minutes from our MLPerf® Training v6.0 submission [3][8]. This confirms that rack-scale systems as complex as GB300 NVL72 can run in a cloud-native format without sacrificing performance.
Updated MLPerf® Inference v6.1 results on NVIDIA Vera Rubin NVL72
Alongside our training submission, we’re updating our MLPerf® Inference v6.1 results. In the original round, we submitted DeepSeek R1 results on a nine-node Vera Rubin NVL72 Preview system with 36 GPUs [9][10]. The updated results come from an Available system and cover two configurations: the same 36 GPUs and the full rack of 72 GPUs [11][12][13][14].
Performance units: tokens per second. Higher values indicate better performance.
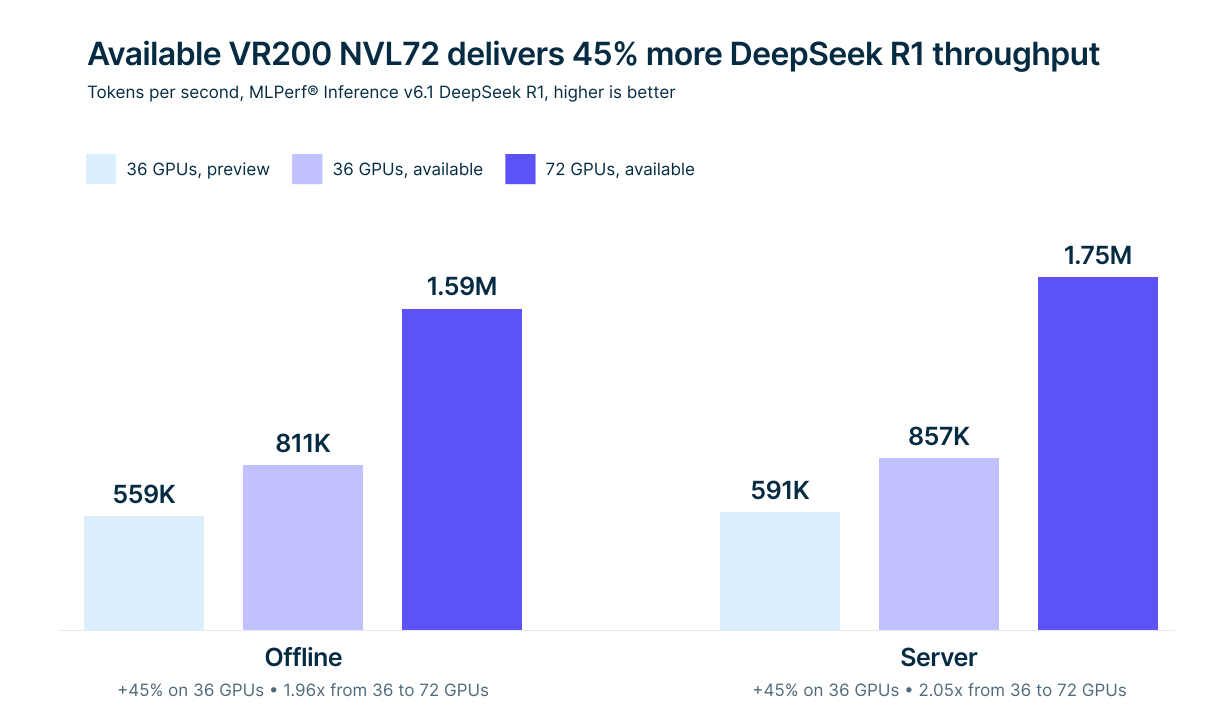
On the same 36 GPUs, the Available system delivered 45% higher throughput in both the offline and server scenarios.
Scaling from 36 GPUs to the full rack, throughput grew 1.96x for offline and 2.05x for server. At full-rack scale, our server result was about 11% higher than the other 72-GPU Vera Rubin NVL72 submission, and our offline result was within 0.4% of it [13][14][15][16].
Together with the training results above, these numbers show our progress on the Vera Rubin generation across both training and inference.
Conclusion
The results of our MLPerf® Training v6.1 submission reflect the progress we’re making on the NVIDIA Vera Rubin Platform ahead of bringing Vera Rubin NVL72 into production on Nebius. We delivered leading training results on Vera Rubin NVL72, higher inference throughput on an available VR200 NVL72 system, and the fastest 64-GPU GB300 NVL72 result on gpt-oss 20B pre-training, in a cloud-native format.
Achieving these results requires constant work across the entire AI infrastructure stack. At Nebius, we test, tune and optimize every layer of our platform, from server acceptance testing to cloud software optimization and multi-stage cluster validation, so that each new NVIDIA platform delivers its full potential in our customer environments.
These results also reflect our close collaboration with NVIDIA, that helps optimize adoption of new GPU platforms and bring them to production faster.
Submitting to MLPerf® round after round is part of how we hold ourselves to account: independently verified results that anyone can check.
To learn how we can support your AI projects at scale, contact us.
*Available and Preview are two of the MLCommons results categories, which indicate a system’s readiness at the time of submission. Learn more in the MLCommons submission rules.
References
- MLPerf® v6.1 Training Closed GPT-OSS-20b (Nebius VR200 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0135. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed Qwen3.5-397B-GRPO (Nebius VR200 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0135. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed GPT-OSS-20b (Nebius GB300 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0049. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed Qwen3.5-397B-GRPO (Nebius GB300 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0049. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed GPT-OSS-20b (VR200 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0120. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed GPT-OSS-20b (VR200 NVL72, 72 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0140. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Training Closed Qwen3.5-397B-GRPO (VR200 NVL72, 64 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.1-0121. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.0 Training Closed GPT-OSS-20b (Nebius GB300 NVL72, 72 GPUs), June 16, 2026, Retrieved from mlcommons.org/benchmarks/training/, entry 6.0-0026. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (Nebius VR200 NVL72, preview category), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0107. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (Nebius VR200 NVL72, preview category), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0135. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (Nebius VR200 NVL72, 36 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0122. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (Nebius VR200 NVL72, 36 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0122. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (Nebius VR200 NVL72, 72 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0123. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (Nebius VR200 NVL72, 72 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0123. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (VR200 NVL72, 72 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0121. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (VR200 NVL72, 72 GPUs), November 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0121. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information. ↵
Explore Nebius Token Factory

See also
Nebius submitted results across seven system configurations to MLPerf® Inference v6.1, our broadest round to date. We took five first-place results, including both DeepSeek R1 scenarios on the full-rack Nebius GB300 NVL72, and were one of only two providers to post preview results on NVIDIA Vera Rubin NVL72, where we led per-GPU Server throughput on DeepSeek R1.
The MLPerf® Storage v3.0 results are in. Nebius Object Storage fed 768 simulated NVIDIA B200 accelerators on the RetinaNet training workload, the highest accelerator count of any submission this round, and ran the highest Unet3D accelerator count among object storage submissions. This post covers the full results, methodology, and what they mean for training directly on object storage.
The results of our MLPerf® Inference v6.0 submission demonstrate Nebius’ ability to maximize efficiency for modern AI inference workloads on the latest NVIDIA Blackwell and Blackwell Ultra platforms.