
MLPerf® Inference v6.1: Previewing NVIDIA Vera Rubin NVL72 and leading full-rack Nebius system with NVIDIA GB300 NVL72 results
MLPerf® Inference v6.1: Previewing NVIDIA Vera Rubin NVL72 and leading full-rack Nebius system with NVIDIA GB300 NVL72 results
Independently verified results carry more weight than any performance claims we at Nebius could make, which is why we submit to MLPerf® Inference every round. Alongside results on NVIDIA Blackwell and Blackwell Ultra systems, we submitted a preview-category result on the Nebius Vera Rubin NVL72, built on NVIDIA’s Vera Rubin platform. Nebius was one of only two submitters in this round with results on Vera Rubin-based hardware.
This was our broadest submission to date. Seven system configurations span a wide range of inference hardware: the rack-scale Nebius system with NVIDIA GB300 NVL72 at three cluster sizes, single-node Nebius system with NVIDIA HGX B300 and NVIDIA HGX B200, a cost-efficient node with 8 NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, and the Nebius VR200 NVL72 preview. We benchmarked three models in this round: DeepSeek R1, Qwen3-VL 235B, and gpt-oss 120B, in both the server and offline scenarios.
Early verified results on the Nebius Vera Rubin NVL72
We’re proud to be one of just two providers that submitted results on NVIDIA Vera Rubin NVL72, which pairs NVIDIA Vera CPUs with NVIDIA Rubin GPUs. Nebius ran DeepSeek R1 on 36 GPUs across nine nodes on a Nebius system with NVIDIA Vera Rubin NVL72 in the preview category.
Preview submissions in this round ran at different cluster sizes; per-GPU throughput is the meaningful comparison point. On that basis, Nebius posted the leading server result at 16,427 tokens/s per GPU [4].
These verified results show the Vera Rubin NVL72 already running frontier-scale reasoning models under benchmark conditions.
Five first-place results
In the MLPerf® Inference v6.1 round Nebius achieved five first-place results across 20 available category entries and submitted an additional preview-category result on the Nebius Vera Rubin NVL72. Below is the table with all submissions:
| System | DeepSeek R1 (server) | DeepSeek R1 (offline) | Qwen3-VL 235B (server) | Qwen3-VL 235B (offline) | gpt-oss 120B (server) | gpt-oss 120B (offline) |
|---|---|---|---|---|---|---|
| Nebius system with NVIDIA HGX B200 (8 NVIDIA Blackwell GPUs) | 55,869 / 2nd [1] | 56,930 / 2nd [5] | — | — | 89,856 / 2nd [13] | 88,491 / 2nd [18] |
| Nebius system with NVIDIA HGX B300 (8 NVIDIA Blackwell Ultra GPUs) | 63,909 / 5th [2] | 69,655 / — [6] | 112.29 / 2nd [9] | 131.48 / 3rd [11] | 108,124 / — [14] | 108,529 / — [19] |
| Nebius system with NVIDIA RTX PRO 6000 (8 GPUs) | — | — | — | — | 14,784 / 2nd [15] | 15,739 / 1st [20] |
| Nebius system with NVIDIA GB300 NVL72 (4 NVIDIA Blackwell Ultra GPUs) | — | — | 64.62 / 2nd [10] | 73.19 / 1st [12] | — | — |
| Nebius system with NVIDIA GB300 NVL72 (8 NVIDIA Blackwell Ultra GPUs) | — | — | — | — | 127,921 / 2nd [16] | 132,236 / 1st [21] |
| Nebius system with NVIDIA GB300 NVL72 (72 NVIDIA Blackwell Ultra GPUs) | 603,023 / 1st [3] | 689,961 / 1st [7] | — | — | 1,122,490 / 2nd [17] | 1,186,750 / 2nd [22] |
| Nebius system with NVIDIA Vera Rubin NVL72 (36 NVIDIA Rubin GPUs, preview) | 591,368 [4] | 558,803 [8] | — | — | — | — |
Performance units: tokens per second for LLM benchmarks (DeepSeek R1, gpt-oss 120B); queries per second for Qwen3-VL 235B (server); samples per second for Qwen3-VL 235B (offline). Higher values indicate better performance. Nebius VR200 NVL72 results were submitted in the preview category on a 36-GPU configuration; rankings are not shown because preview submissions in this round ran at different cluster sizes.
The GB300 NVL72 ran as bare metal, and the rest ran as virtual machines on Nebius AI Cloud.
Leading full-rack performance on Nebius system with NVIDIA GB300 NVL72
On the full-rack Nebius system with NVIDIA GB300 NVL72, 72 NVIDIA Blackwell Ultra GPUs across 18 nodes served large-scale inference workloads. With this configuration, we ranked first in both the server and offline scenarios for DeepSeek R1, at 603,023 and 689,961 tokens/s respectively [3][7].
The same full-rack system sustained over 1.1 million tokens/s on gpt-oss 120B in both scenarios [17][22]. That throughput scaled almost linearly: moving from the eight-GPU GB300 NVL72 configuration to the NVIDIA GB300 NV72 rack, a 9x increase in GPUs, it delivered 8.8x higher server throughput and 9.0x higher offline throughput [16][17][21][22]. Only two submitters ran that eight-GPU configuration. Nebius posted the top offline result for gpt-oss 120B and came within 0.2% of the top server result [16][21].
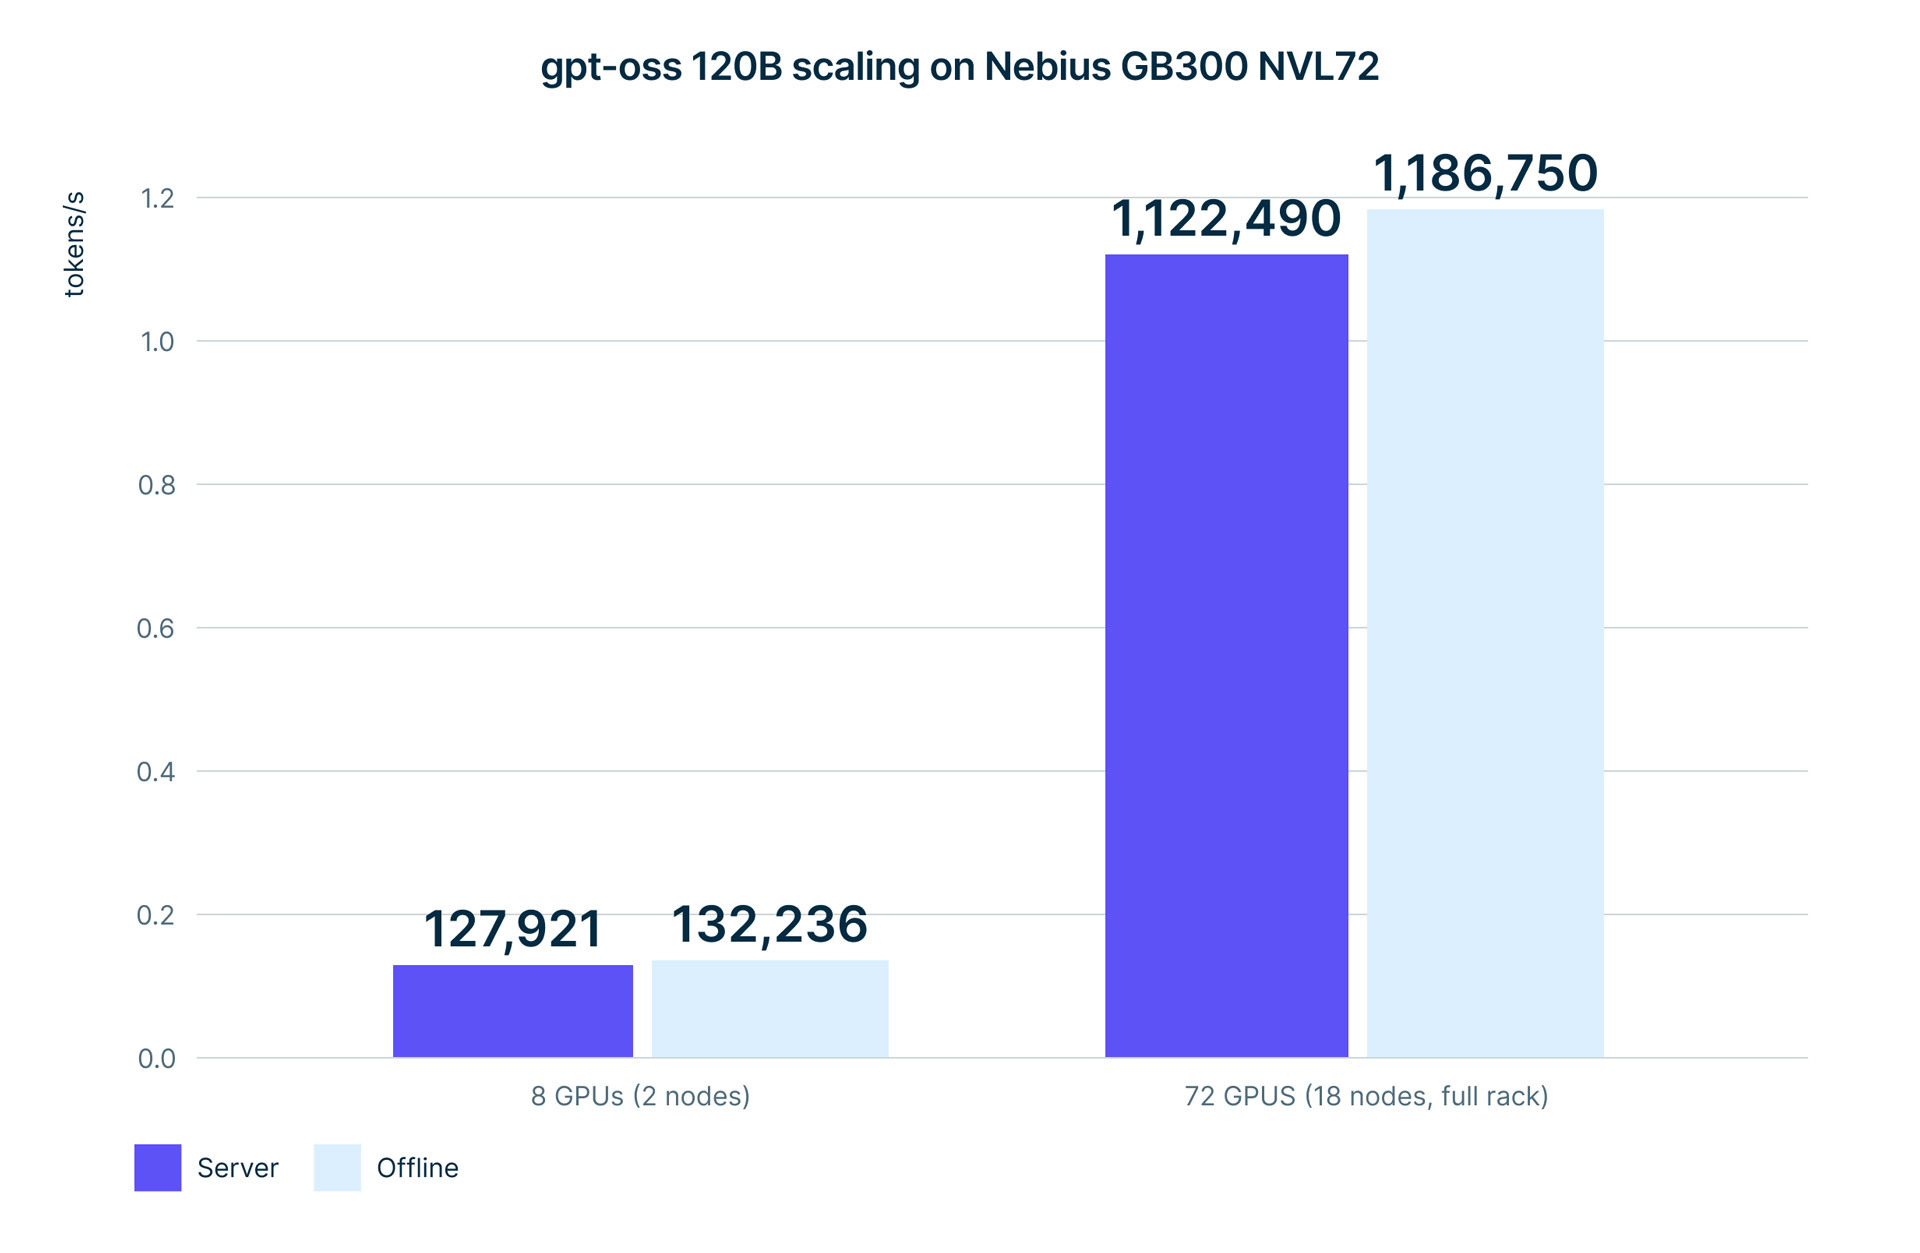 Figure 1. gpt-oss 120B throughput scaling from 8 to 72 GPUs on the Nebius system with NVIDIA GB300 NVL72 [16][17][21][22].
Consistent performance from single node to full rack
The MLPerf® Inference v6.1 results show how inference performance improves across successive NVIDIA platforms. For DeepSeek R1, moving from the Nebius system with NVIDIA HGX B200 to the Nebius system with NVIDIA HGX B300 raised server throughput from 55,869 to 63,909 tokens/s on identical eight-GPU configurations [1][2]. The same pattern holds for gpt-oss 120B, from 89,856 to 108,124 tokens/s [13][14].
At the other end of the range, we benchmarked a node with 8 NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, the most cost-efficient tier for applied inference workloads. That node posted the fastest offline result among all 8x NVIDIA RTX PRO 6000 GPU submissions for gpt-oss 120B and came within 0.3% of the best server result [15][20].
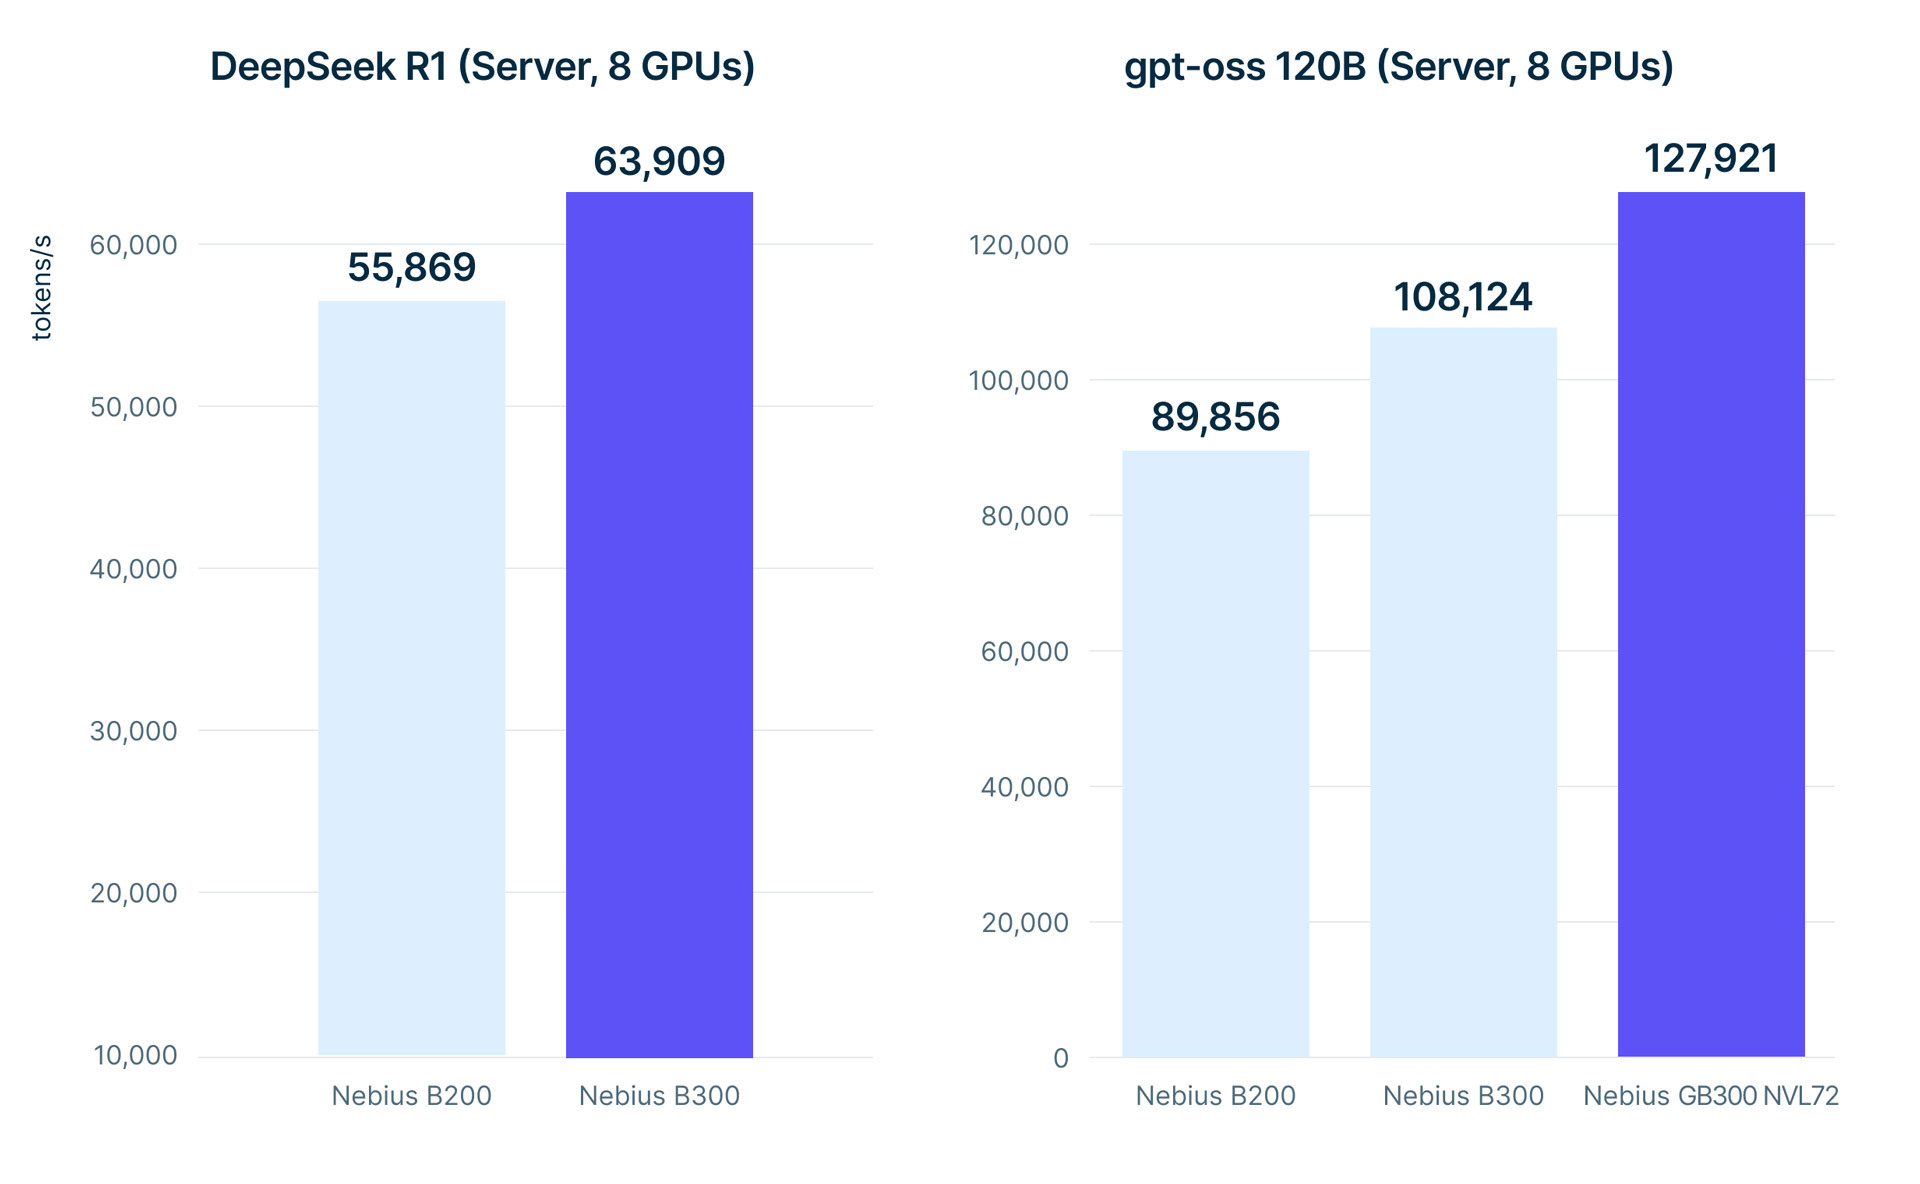 Figure 2. DeepSeek R1 and gpt-oss 120B server throughput across 8-GPU configurations of the Nebius system with NVIDIA HGX B200, Nebius system with NVIDIA HGX B300, and Nebius system with NVIDIA GB300 NVL72. [1][2][13][14][16]
Conclusion
Our MLPerf® Inference v6.1 results tell two stories. Nebius delivered verified leading performance, including first-place results at full-rack scale. And our preview results show frontier-model inference already running on the NVIDIA Vera Rubin NVL72.
Achieving these results requires constant work across the entire AI infrastructure stack. At Nebius, we continuously test, tune, and optimize our platform to ensure that the newest NVIDIA hardware delivers its full potential in our customer environments. These results also reflect our close collaboration with NVIDIA, where joint engineering efforts help bring new GPU platforms to production environments faster.
To learn how we can support your AI inference workloads at scale, get in touch.
References
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (NVIDIA HGX B200), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0077. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (Nebius GB300 NVL72, 72 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0080. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 server (Nebius VR200 NVL72, preview category), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0107. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (NVIDIA HGX B200), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0077. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (Nebius GB300 NVL72, 72 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0080. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed DeepSeek R1 offline (Nebius VR200 NVL72, preview category), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0107. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed Qwen3-VL 235B server (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed Qwen3-VL 235B server (Nebius GB300 NVL72, 4 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0079. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed Qwen3-VL 235B offline (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed Qwen3-VL 235B offline (Nebius GB300 NVL72, 4 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0079. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B server (NVIDIA HGX B200), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0077. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B server (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B server (8x NVIDIA RTX PRO 6000), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0082. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B server (Nebius GB300 NVL72, 8 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0081. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B server (Nebius GB300 NVL72, 72 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0080. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B offline (NVIDIA HGX B200), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0077. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B offline (NVIDIA HGX B300), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0078. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B offline (8x NVIDIA RTX PRO 6000), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0082. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B offline (Nebius GB300 NVL72, 8 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0081. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
- MLPerf® v6.1 Inference Closed gpt-oss 120B offline (Nebius GB300 NVL72, 72 GPUs), September 16, 2026, Retrieved from mlcommons.org/benchmarks/inference-datacenter/, entry 6.1-0080. Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See mlcommons.org for more information.↵
Explore Nebius Token Factory
See also
The MLPerf® Storage v3.0 results are in. Nebius Object Storage fed 768 simulated NVIDIA B200 accelerators on the RetinaNet training workload, the highest accelerator count of any submission this round, and ran the highest Unet3D accelerator count among object storage submissions. This post covers the full results, methodology, and what they mean for training directly on object storage.
Nebius is he first AI cloud to adopt NVIDIA Groq 3 LPX, to Nebius Token Factory, adding generation-optimized performance purpose-built for agentic AI. Independently benchmarked at 3,400 output tokens per second for a single user on Google Gemma 4 31B, NVIDIA Groq 3 LPX pairs with NVIDIA Vera Rubin NVL72 so developers get it through the same Token Factory catalog and API they already use.
The results of our MLPerf® Inference v6.0 submission demonstrate Nebius’ ability to maximize efficiency for modern AI inference workloads on the latest NVIDIA Blackwell and Blackwell Ultra platforms.