
Process documents faster, on open models at scale
Nebius gives you open-source vision models, structured extraction APIs, and scalable GPU compute to build document intelligence pipelines — without paying proprietary per-page pricing.
Why build document intelligence on Nebius
Vision models for document understanding
Token Factory serves VLMs like Qwen2.5-VL and Nemotron Nano 2 VL for layout analysis, table extraction, and OCR.
Structured extraction at any scale
Structured output and JSON mode for reliable field extraction from invoices, contracts, forms, and any document type.
GPUs purpose-built for visual compute
NVIDIA L40S and RTX PRO 6000 optimized for vision model inference. Scale throughput with Capacity Blocks.
A developer platform, not just compute
Manage infrastructure, data, and models from a single console — Managed Kubernetes and PostgreSQL for your stack, Token Factory for inference, and built-in observability across all of it.
Enterprise-ready from day one
Deploy with built-in network isolation, identity management, audit logging, and certifications your customers already require. HIPAA-grade infrastructure available.
Everything you need to build document intelligence at scale
Nebius provides vision models, extraction APIs, and infrastructure for production document pipelines. Every component is open and replaceable — bring your own parsers, models, and storage alongside.
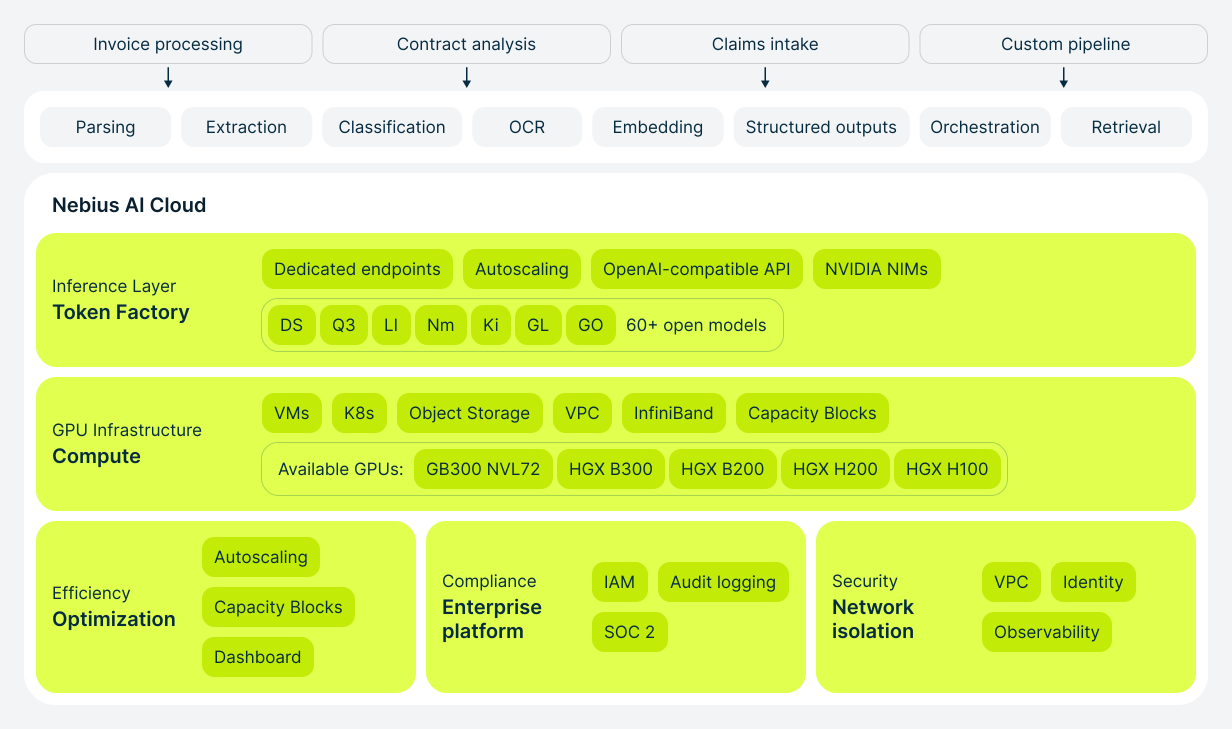
Native capabilities for document intelligence
What Token Factory covers across the document pipeline — from parsing and extraction to classification and search.
Parse and understand documents
Analyze layouts, extract tables, and run OCR with Qwen2.5-VL and Nemotron Nano 2 VL via /v1/chat/completions.

Structured extraction
Pull fields, entities, and tables into typed schemas with JSON mode and structured output via the Tool use API.
Document classification
Classify document types, route to the right extraction schema, and trigger downstream workflows.

Search and index documents
Create semantic document search with BAAI/bge-en-icl via /v1/embeddings. Pair with Qdrant or Weaviate.

Process documents at scale
Orchestrate batch pipelines on Managed Kubernetes. Distribute high-volume workloads with Anyscale/Ray.

Store extracted data
Managed PostgreSQL for extracted fields and metadata. Object Storage for raw documents and processed outputs.


