
Qwen models inference
Run Qwen models for general-purpose text generation, reasoning, coding, retrieval, and embeddings through Nebius Token Factory’s OpenAI-compatible APIs.
Qwen3.5-397B-A17B
Evaluate the current flagship Qwen route for chat, reasoning, coding, retrieval-augmented generation, and agent workflows.
Qwen3-30B-A3B-Instruct-2507
Use a smaller MoE model for cost-sensitive chat, code, tool use, and high-volume text inference.
Qwen3-Next-80B-A3B-Thinking
Deploy a dedicated reasoning model for math, code, planning, and longer multi-step tasks.
Qwen3-Embedding-8B
Build multilingual semantic search, retrieval, clustering, and classification with a 4,096-dimensional embedding model.
Qwen3-Coder-480B-A35B-Instruct
Use a dedicated code-focused model for repository-scale software engineering and tool-driven development workflows.
Public and dedicated paths
Start with public models where available, then use model-specific dedicated capacity or fine-tuning paths for selected workloads.
Choose your Qwen model
Qwen3.5-397B-A17B
Flagship Qwen model for complex text, reasoning, coding, and agent workflows
Best for: high-quality chat, reasoning, coding, RAG, and tool use
- 262K-token context
- FP4 and BF16 configurations listed
- Tool calling and reasoning available
- Public endpoint available
- Token Factory route currently listed as text-to-text
- $0.60 / 1M input tokens · $3.60 / 1M output tokens
Qwen3-30B-A3B-Instruct-2507
Efficient MoE instruct model for chat, coding, and tool use
Best for: cost-sensitive assistants, code, tools, and high-volume text inference
- 31B parameters
- 262K-token context
- FP8 and BF16 configurations listed
- Tool calling available
- Public and dedicated endpoints available
- Full fine-tuning, LoRA fine-tuning, and custom speculator paths listed
- $0.10 / 1M input tokens · $0.30 / 1M output tokens
Qwen3-Embedding-8B
Multilingual embedding model for retrieval and semantic search
Best for: RAG, semantic search, clustering, and classification
- 8B parameters
- 41K-token context
- 4,096-dimensional embeddings
- Public and dedicated endpoints available
Qwen3-Next-80B-A3B-Thinking
Thinking-optimized MoE for deliberate multi-step reasoning
Best for: math, coding, structured deliberation, and complex planning
- 81B parameters
- 128K-token context
- FP8 serving configuration
- Tool calling and reasoning available
- Dedicated endpoint available; no public endpoint currently listed
Qwen3-Coder-480B-A35B-Instruct
Large code-focused MoE for software-engineering workflows
Best for: repository-scale coding, development agents, and tool-driven engineering
- 480B parameters
- 262K-token context
- FP8 serving configuration
- Tool calling available
- Dedicated endpoint and full fine-tuning available; no public endpoint currently listed
Benchmarks
Qwen3.5-397B-A17B
Flagship reasoning and multimodal work
Qwen reports:
- 87.8 on MMLU-Pro
- 88.4 on GPQA
- 90.8 on OmniDocBench
- 76.4 on SWE-Bench Verified.
A strong general-purpose choice spanning reasoning, coding, agents, and document understanding.
Qwen3-30B-A3B-Instruct-2507
Efficient instruction following
Qwen reports:
- 78.4 on MMLU-Pro
- 70.4 on GPQA,
- 82.5 on RULER at 256K.
It offers broad instruction-following and long-context capability with 3.3B active parameters.
Qwen3-Embedding-8B
Multilingual retrieval
Qwen reports a 70.58 mean on multilingual MTEB and 75.22 on MTEB English v2.
Designed for multilingual search, retrieval, classification, and RAG.
Qwen3-Next
Reasoning and coding agents
Qwen3-Next-80B-A3B-Thinking reports:
- 87.8 on AIME25
- 68.7 on LiveCodeBench v6
- 72.0 on BFCL-v3.
Qwen3-Coder
Reasoning and coding agents
Qwen3-Coder-480B-A35B-Instruct is specialized for repository-scale agentic coding and reports 38.7 on SWE-Bench Pro.
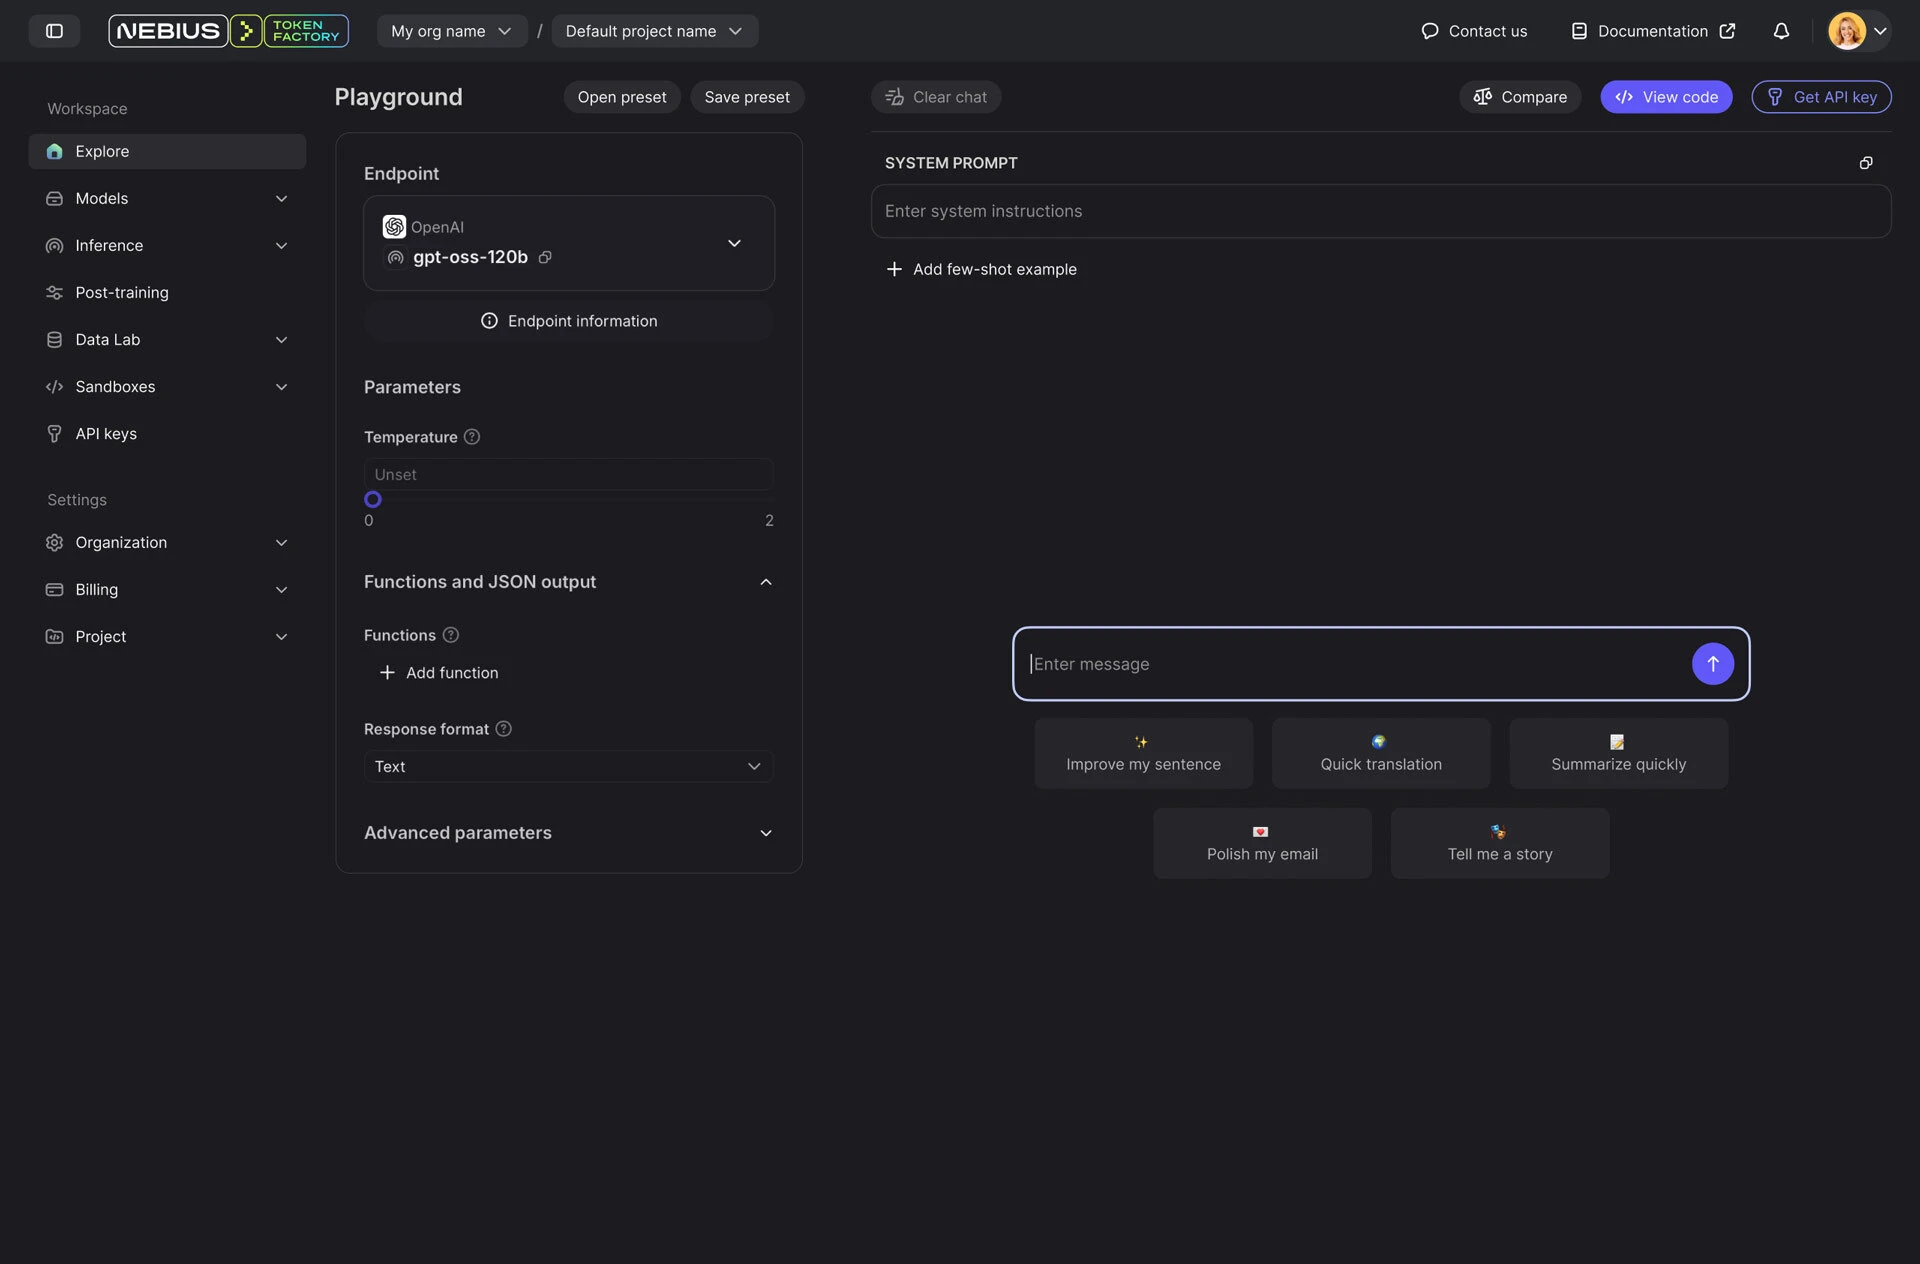
Compare public Qwen models on your workload
Compare public Qwen models on your workload
Use the Playground to compare public text models on the same prompts. For retrieval workloads, call Qwen3-Embedding-8B through the embeddings API and evaluate it on your own corpus. Dedicated-only models require a separate deployment.
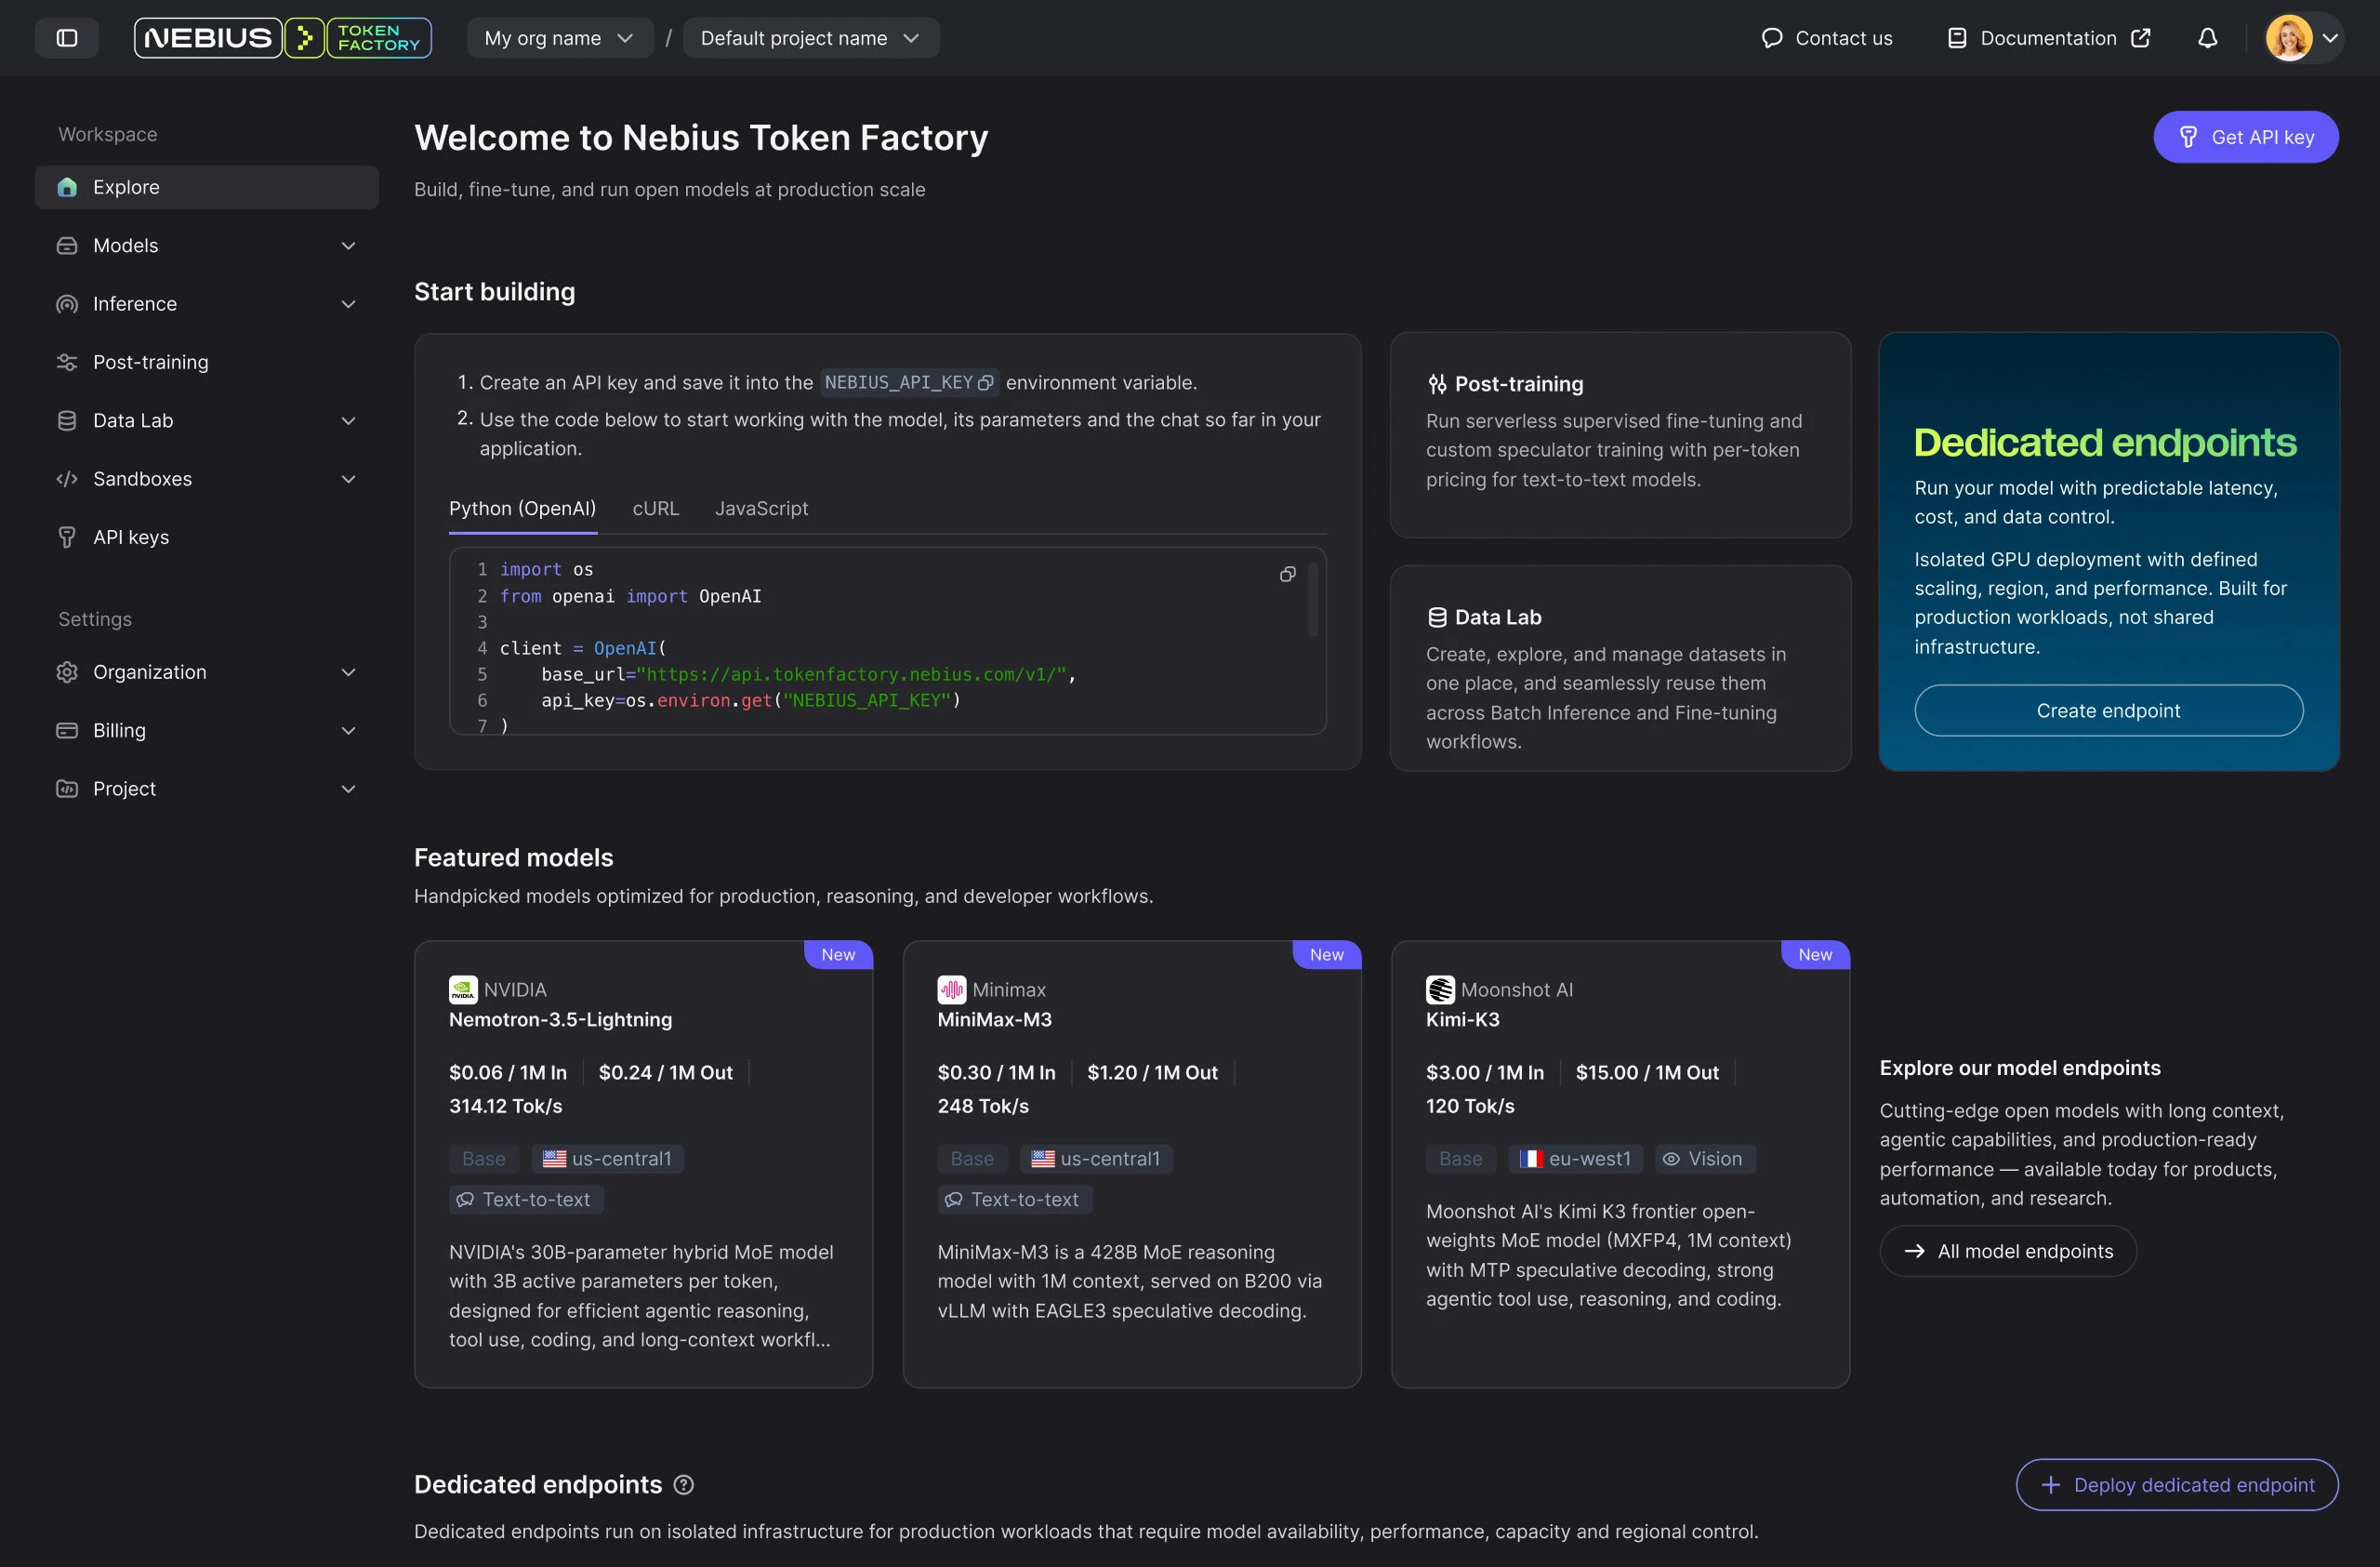
Familiar APIs at your fingertips
Use the OpenAI-compatible chat API for text models and the embeddings API for Qwen3-Embedding-8B.
import openai
import os

client = openai.OpenAI(
    api_key=os.environ.get("NEBIUS_API_KEY"),
    base_url='https://api.tokenfactory.nebius.com/'
)

completion = client.chat.completions.create(
    messages=[{
        'role': 'user',
        'content': 'What is the answer to all questions?'
    }],
    model='Qwen/Qwen3.5-397B-A17B'
)
Choose how to run Qwen
Deployment option
Best for
What you get
Public endpoints
Evaluation, prototyping, retrieval experiments, and variable traffic
Pay-per-token access for models currently listed as public
Dedicated endpoints
Workloads that need isolated capacity or regional control
Model-specific availability; confirm the selected Qwen model and configuration
Fine-tuning or custom deployment
Adapted models and specialized requirements
Model-specific training and deployment paths, subject to technical review
Frequently asked questions
Start with Qwen3.5-397B-A17B for the current flagship public text route. Use Qwen3-30B-A3B-Instruct-2507 for lower-cost text inference, Qwen3-Embedding-8B for retrieval, Qwen3-Next for dedicated reasoning, and Qwen3-Coder for a dedicated coding workflow.