
NVIDIA Nemotron models inference
Run NVIDIA Nemotron models for efficient reasoning, coding, multi-agent systems, and long-context workloads through Nebius Token Factory’s OpenAI-compatible API.
From compact agents to frontier reasoning
Choose a 30B-efficient model, a balanced 120B model, or a 550B model for the most demanding reasoning and multi-agent tasks.
Nemotron 3.5 Lightning
Use a 30B hybrid MoE model with 3B active parameters for efficient agentic reasoning, coding, and tool use.
Visual understanding and complex reasoning
Use Nemotron 3.5 Super VL for agents working with documents and visual information, and Nemotron 3 Ultra for demanding reasoning tasks.
Up to 1M-token context
Work across long research trails, large documents, codebases, and extended agent histories.
Agent-ready capabilities
Build applications that combine reasoning with external functions and structured multi-step execution.
Public and dedicated paths
Evaluate the public Nemotron lineup quickly, with model-specific dedicated availability for selected workloads.
Choose your Nemotron model
Nemotron-3.5-Lightning
Efficient 30B hybrid MoE model for agentic reasoning and coding
Best for: high-volume agents, coding, tool use, reasoning, and long-context workflows
- 30B total parameters with 3B active per token
- 1,024K-token context
- BF16 serving configuration
- Public endpoint available
- $0.06 / 1M input tokens · $0.24 / 1M output tokens
Nemotron-3-Ultra-550b-a55b
Large hybrid MoE model for demanding multi-agent and reasoning workloads
Best for: complex reasoning, multi-agent systems, research, and long-running tasks
- 550B hybrid MoE model
- 1,024K-token context
- FP4 serving configuration
- Public endpoint available
- $1.00 / 1M input tokens · $3.00 / 1M output tokens
NVIDIA Nemotron 3.5 Super VL
Visual understanding, reasoning and tool use for agent workflows
Best for: document understanding, web research and agents working with visual information
- 120B total parameters, 12B active
- $0.30 / 1M input tokens
- $0.90 / 1M output tokens
Nemotron-3-Nano-30B-A3B
Compact MoE model for efficient reasoning, chat, coding, and RAG
Best for: cost-efficient agents, multilingual chat, coding, retrieval, and high-volume inference
- 30B total parameters
- 262K-token context
- FP8 serving configuration
- Public endpoint available
- $0.06 / 1M input tokens · $0.24 / 1M output tokens
Benchmarks
NVIDIA reports these results using model- and benchmark-specific evaluation harnesses. Scores from different cards should not be treated as direct endpoint comparisons.
They do not guarantee Token Factory throughput, latency, or availability.
Nemotron 3 Ultra
Frontier agents and reasoning
NVIDIA reports:
- 87.0 on GPQA
- 70.7 on SWE-Bench Verified
- 56.4 on Terminal-Bench 2.1
Designed for complex agents, software engineering, and demanding analytical workloads.
Nemotron 3 Super
Reasoning and long-context work
NVIDIA reports:
- 94.73 on HMMT February 2025 with tools
- 60.47 on SWE-Bench using OpenHands
- 96.30 on RULER at 256K
A strong candidate for collaborative agents and long-context workflows.
Nemotron 3.5 Lightning and Nemotron 3 Nano
Efficient reasoning
Both activate approximately 3B parameters.
- Lightning reports 85.37 on PinchBench and 71.88 on IFBench
- Nano reports 99.2 on AIME25 with tools and 53.8 on BFCL v4
These models target more compute-efficient reasoning, instruction following, and tool use.
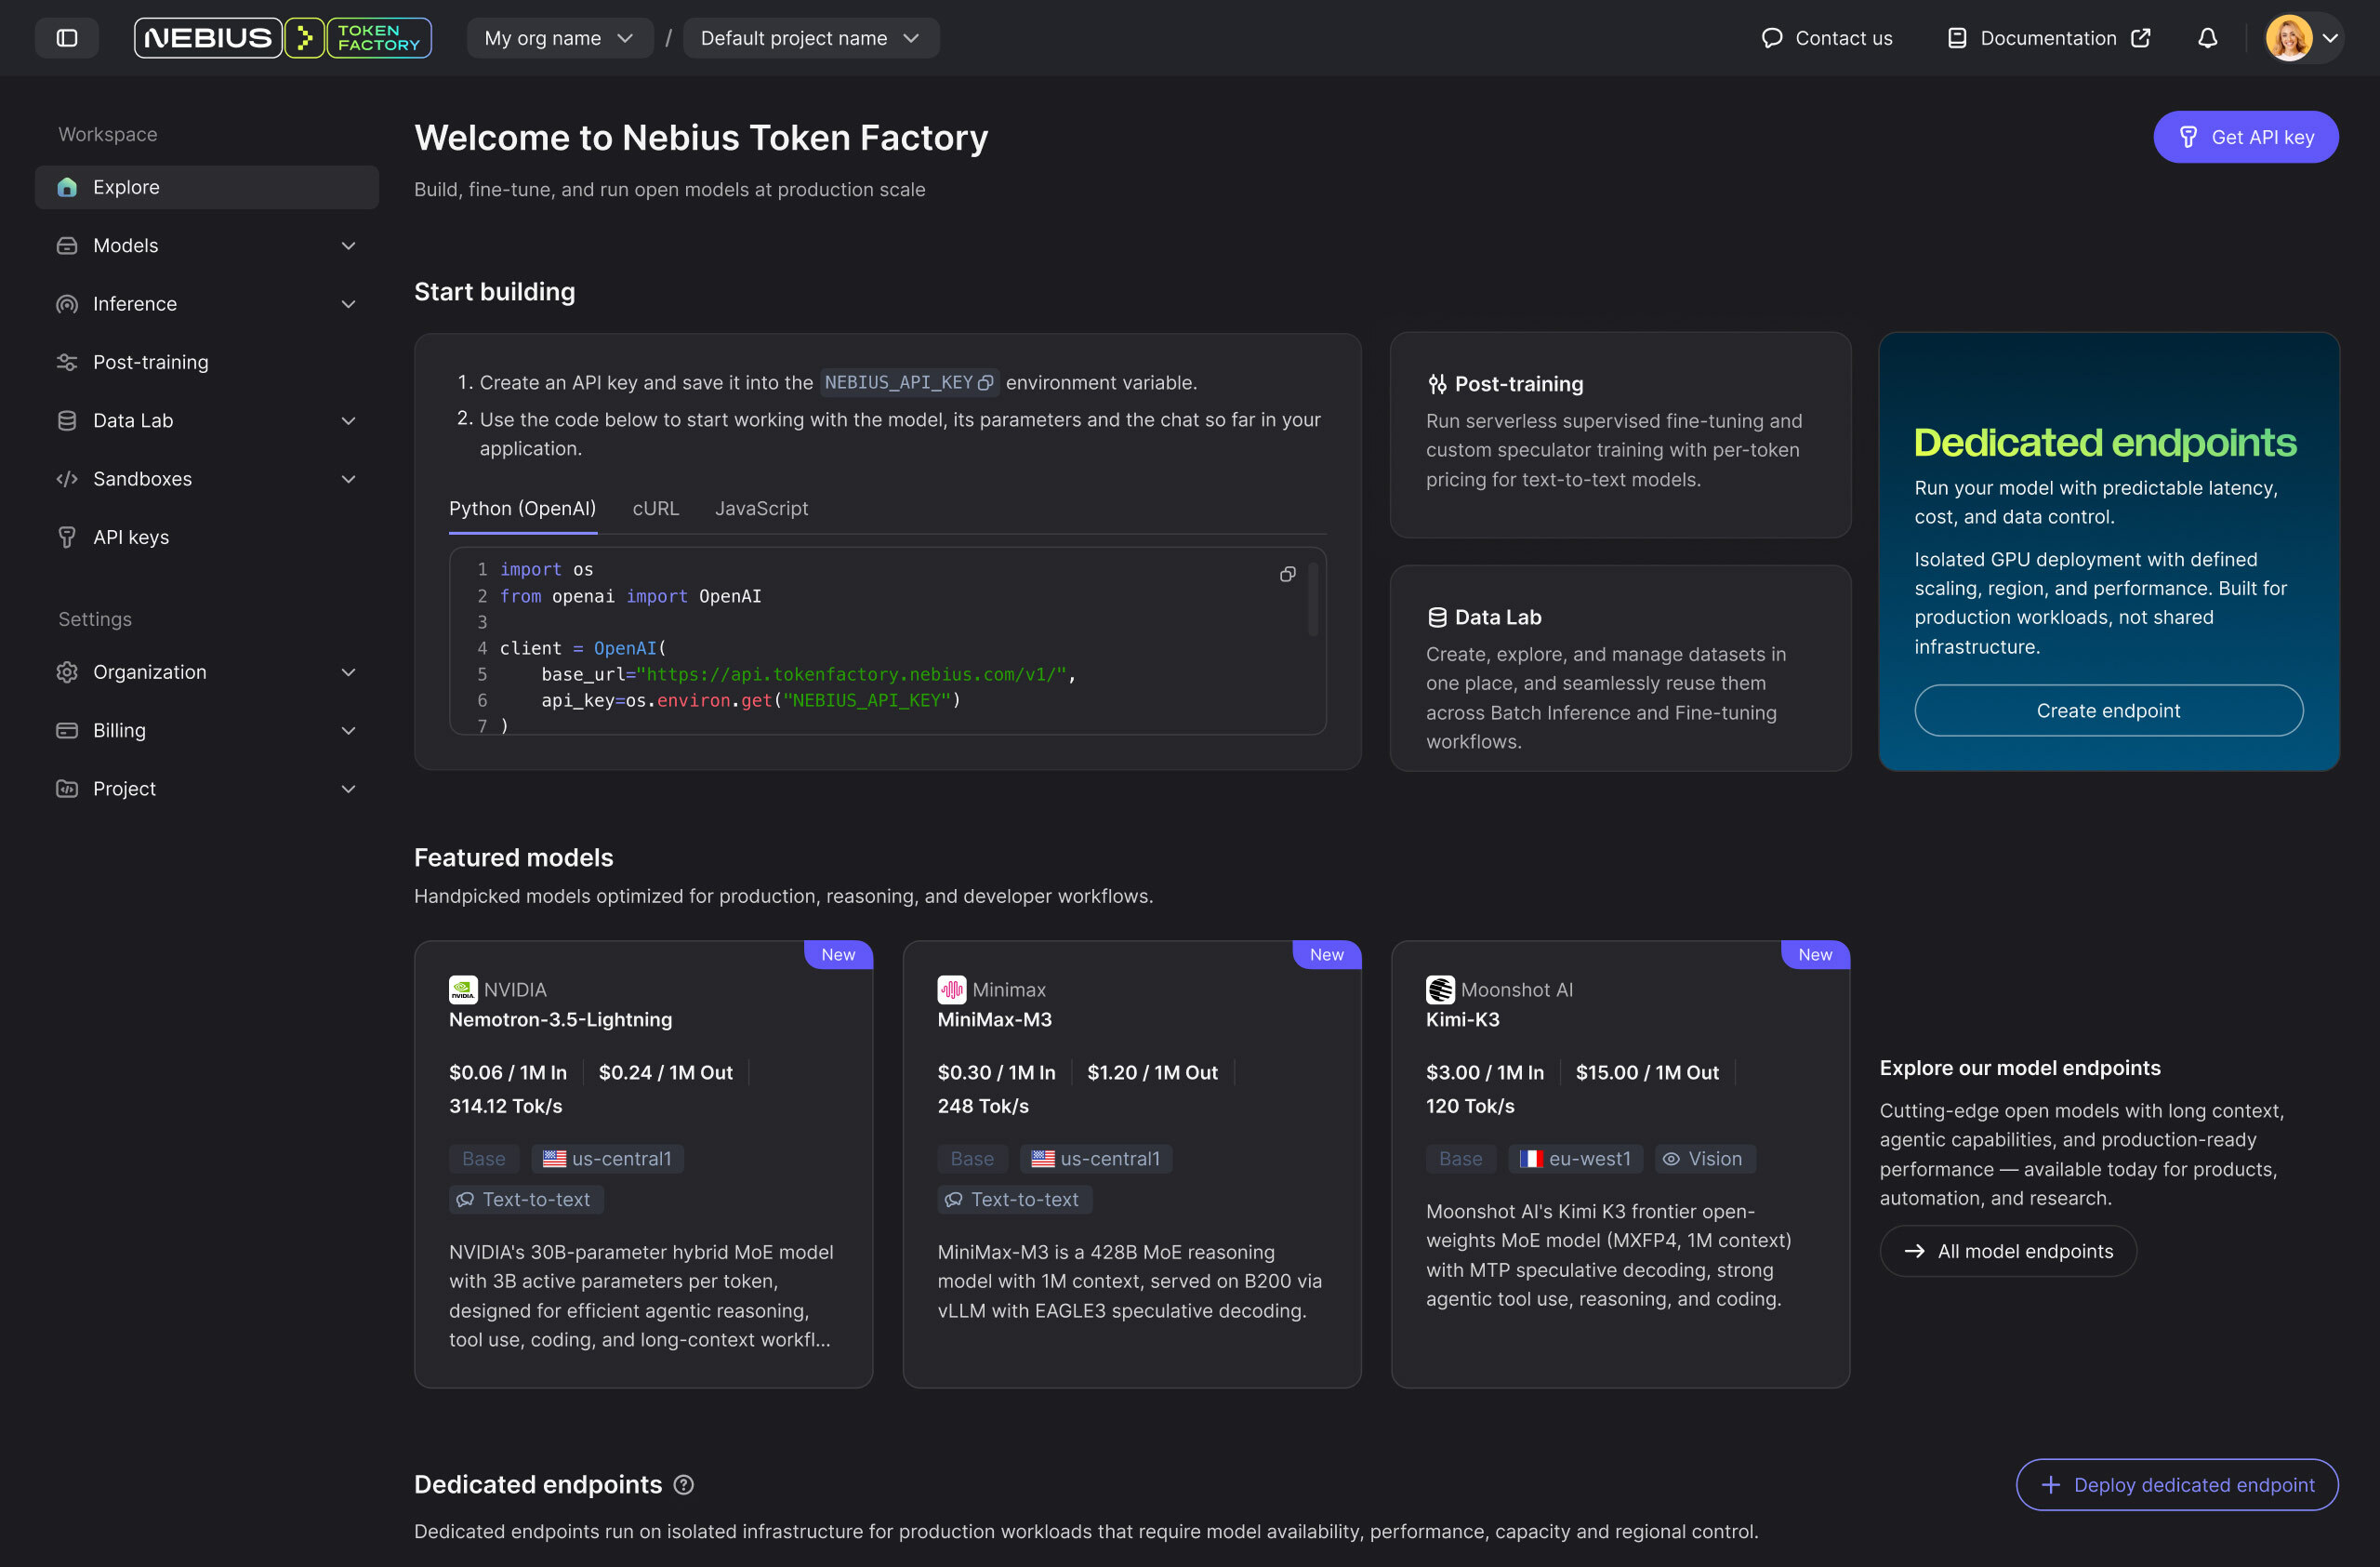
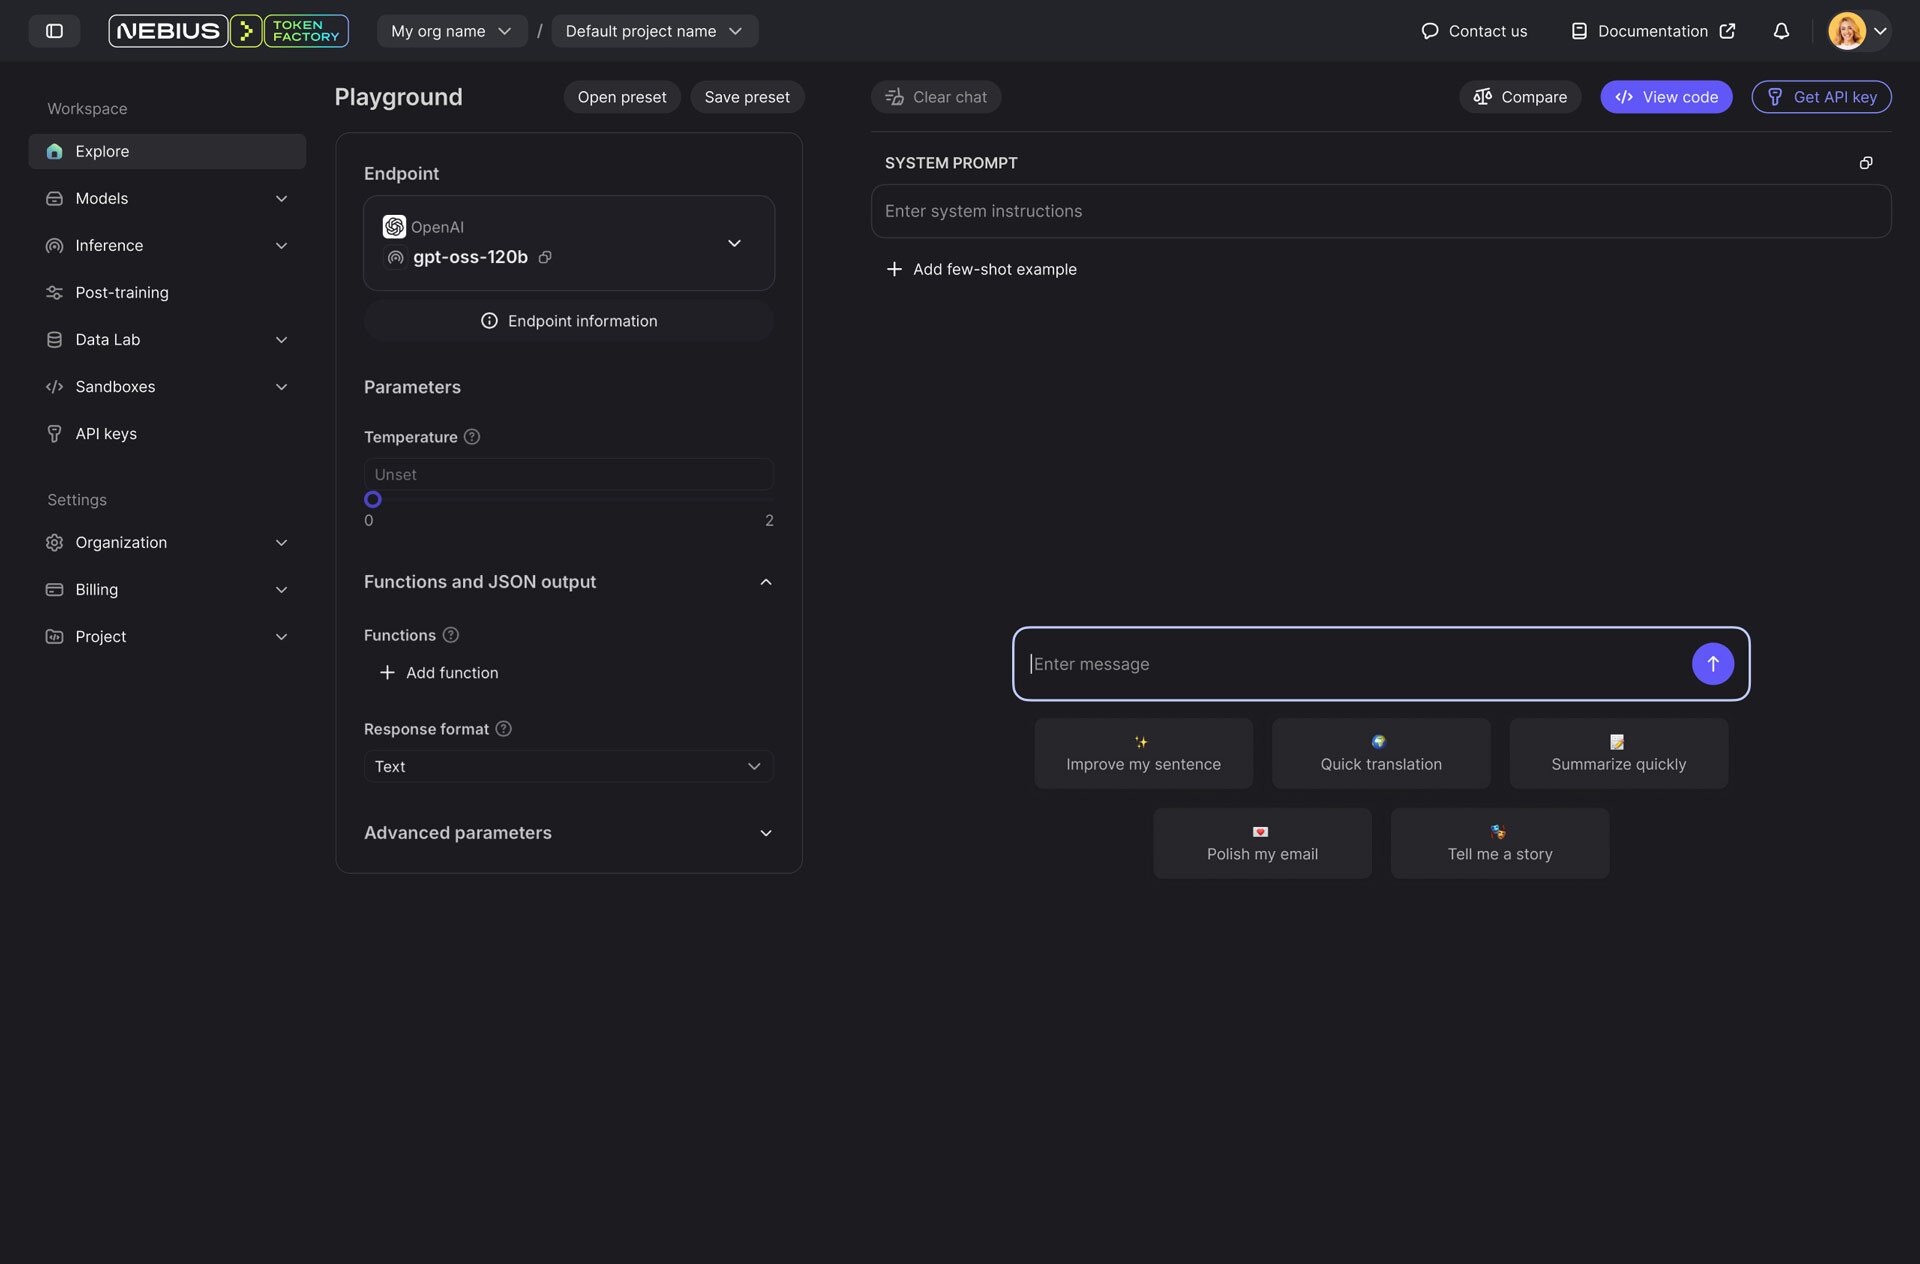
A simple and friendly UI for a smooth user experience
A simple and friendly UI for a smooth user experience
Use the Playground to compare Lightning, Ultra, Super VL, and Nano on your own reasoning, coding, tool-use, and long-context tasks. Refine prompts and export an API-ready request when you are ready.
Familiar API at your fingertips
Use the OpenAI-compatible API and switch between Nemotron models by changing the model ID.
import openai
import os

client = openai.OpenAI(
    api_key=os.environ.get("NEBIUS_API_KEY"),
    base_url="https://api.tokenfactory.nebius.com/v1/"
)

completion = client.chat.completions.create(
    messages=[{
        'role': 'user',
        'content': 'What is the answer to all questions?'
    }],
    model="nvidia/Nemotron-3.5-Super-VL"
)
Choose how to run Nemotron
Deployment option
Best for
What you get
Public endpoints
Evaluation, prototyping, and variable traffic
Pay-per-token access to the public Nemotron lineup with no deployment required
Dedicated endpoints
Workloads that need isolated capacity or regional control
Model-specific availability; confirm the selected model before committing
Custom deployments
Private weights or specialized requirements
Workload-specific sizing and deployment support
Frequently asked questions
Start with Nemotron 3.5 Lightning for efficient current-generation reasoning and coding. Choose Nano for cost-efficient high-volume work, Super VL for document understanding and visual agent workflows, or Ultra for the most demanding reasoning tasks.