
Kimi models inference
Run Moonshot AI’s current Kimi models for long-context agents, coding, reasoning, research, and multimodal workflows through Nebius Token Factory’s OpenAI-compatible API.
Kimi-K3 for long-running agents
Use Kimi-K3 for demanding reasoning, coding, tool use, and multimodal work across a 1,024K-token context.
Kimi-K2.7-Code for software engineering
Work across repositories, tools, and long implementation trajectories with a code-focused reasoning model.
Text and vision with Kimi-K2.6
Build applications that combine visual understanding, research, reasoning, and tool-driven execution.
Up to 1M-token context
Keep large codebases, research trails, documents, and agent histories in one working context.
Reasoning and tool calling
Connect Kimi models to external functions and orchestrate multi-step application logic.
Start with a shared API
Evaluate the current Kimi lineup through public Token Factory endpoints without provisioning infrastructure.
Choose your Kimi model
Kimi-K3
Frontier multimodal model for long-running agents and complex reasoning
Best for: advanced agents, research, coding, reasoning, tool use, and image-aware workflows
- 1,024K-token context
- FP4 serving configuration
- Vision input, tool calling, and reasoning available
- Public endpoint available
- $3.00 / 1M input tokens · $15.00 / 1M output tokens
Kimi-K2.7-Code
Code-focused reasoning model for long-context software engineering
Best for: coding agents, repository-scale work, tools, and long implementation trajectories
- 256K-token context
- FP4 serving configuration
- Tool calling and reasoning available
- Public endpoint available
- $0.95 / 1M input tokens · $4.00 / 1M output tokens
Kimi-K2.6
Native multimodal model for research, reasoning, coding, and visual work
Best for: deep research, multimodal agents, coding, and image understanding
- 256K-token context
- INT4 serving configuration
- Vision input, tool calling, and reasoning available
- Public endpoint available
- $0.95 / 1M input tokens · $4.00 / 1M output tokens
Benchmarks
Kimi K3
Agentic research and coding
Moonshot reports:
- 95.0 F1 on DeepSearchQA
- 94.5 on MCPMark-Verified
- 88.3 on Terminal-Bench 2.1
A strong candidate for tool-using research and long-horizon coding agents.
Kimi K2.7
Code — software-engineering agents
Compared with K2.6, K2.7 Code improves from 50.9 to 62.0 on Kimi Code Bench v2 and from 72.8 to 81.1 on MCPMark-Verified, while using approximately 30% fewer thinking tokens.
Built for multi-step software-engineering work.
Kimi K2.6
Coding, reasoning, and vision
Moonshot reports:
- 80.2 on SWE-Bench Verified
- 90.5 on GPQA Diamond
- 79.4 on MMMU-Pro
A balanced option when software engineering, general reasoning, and visual inputs all matter.
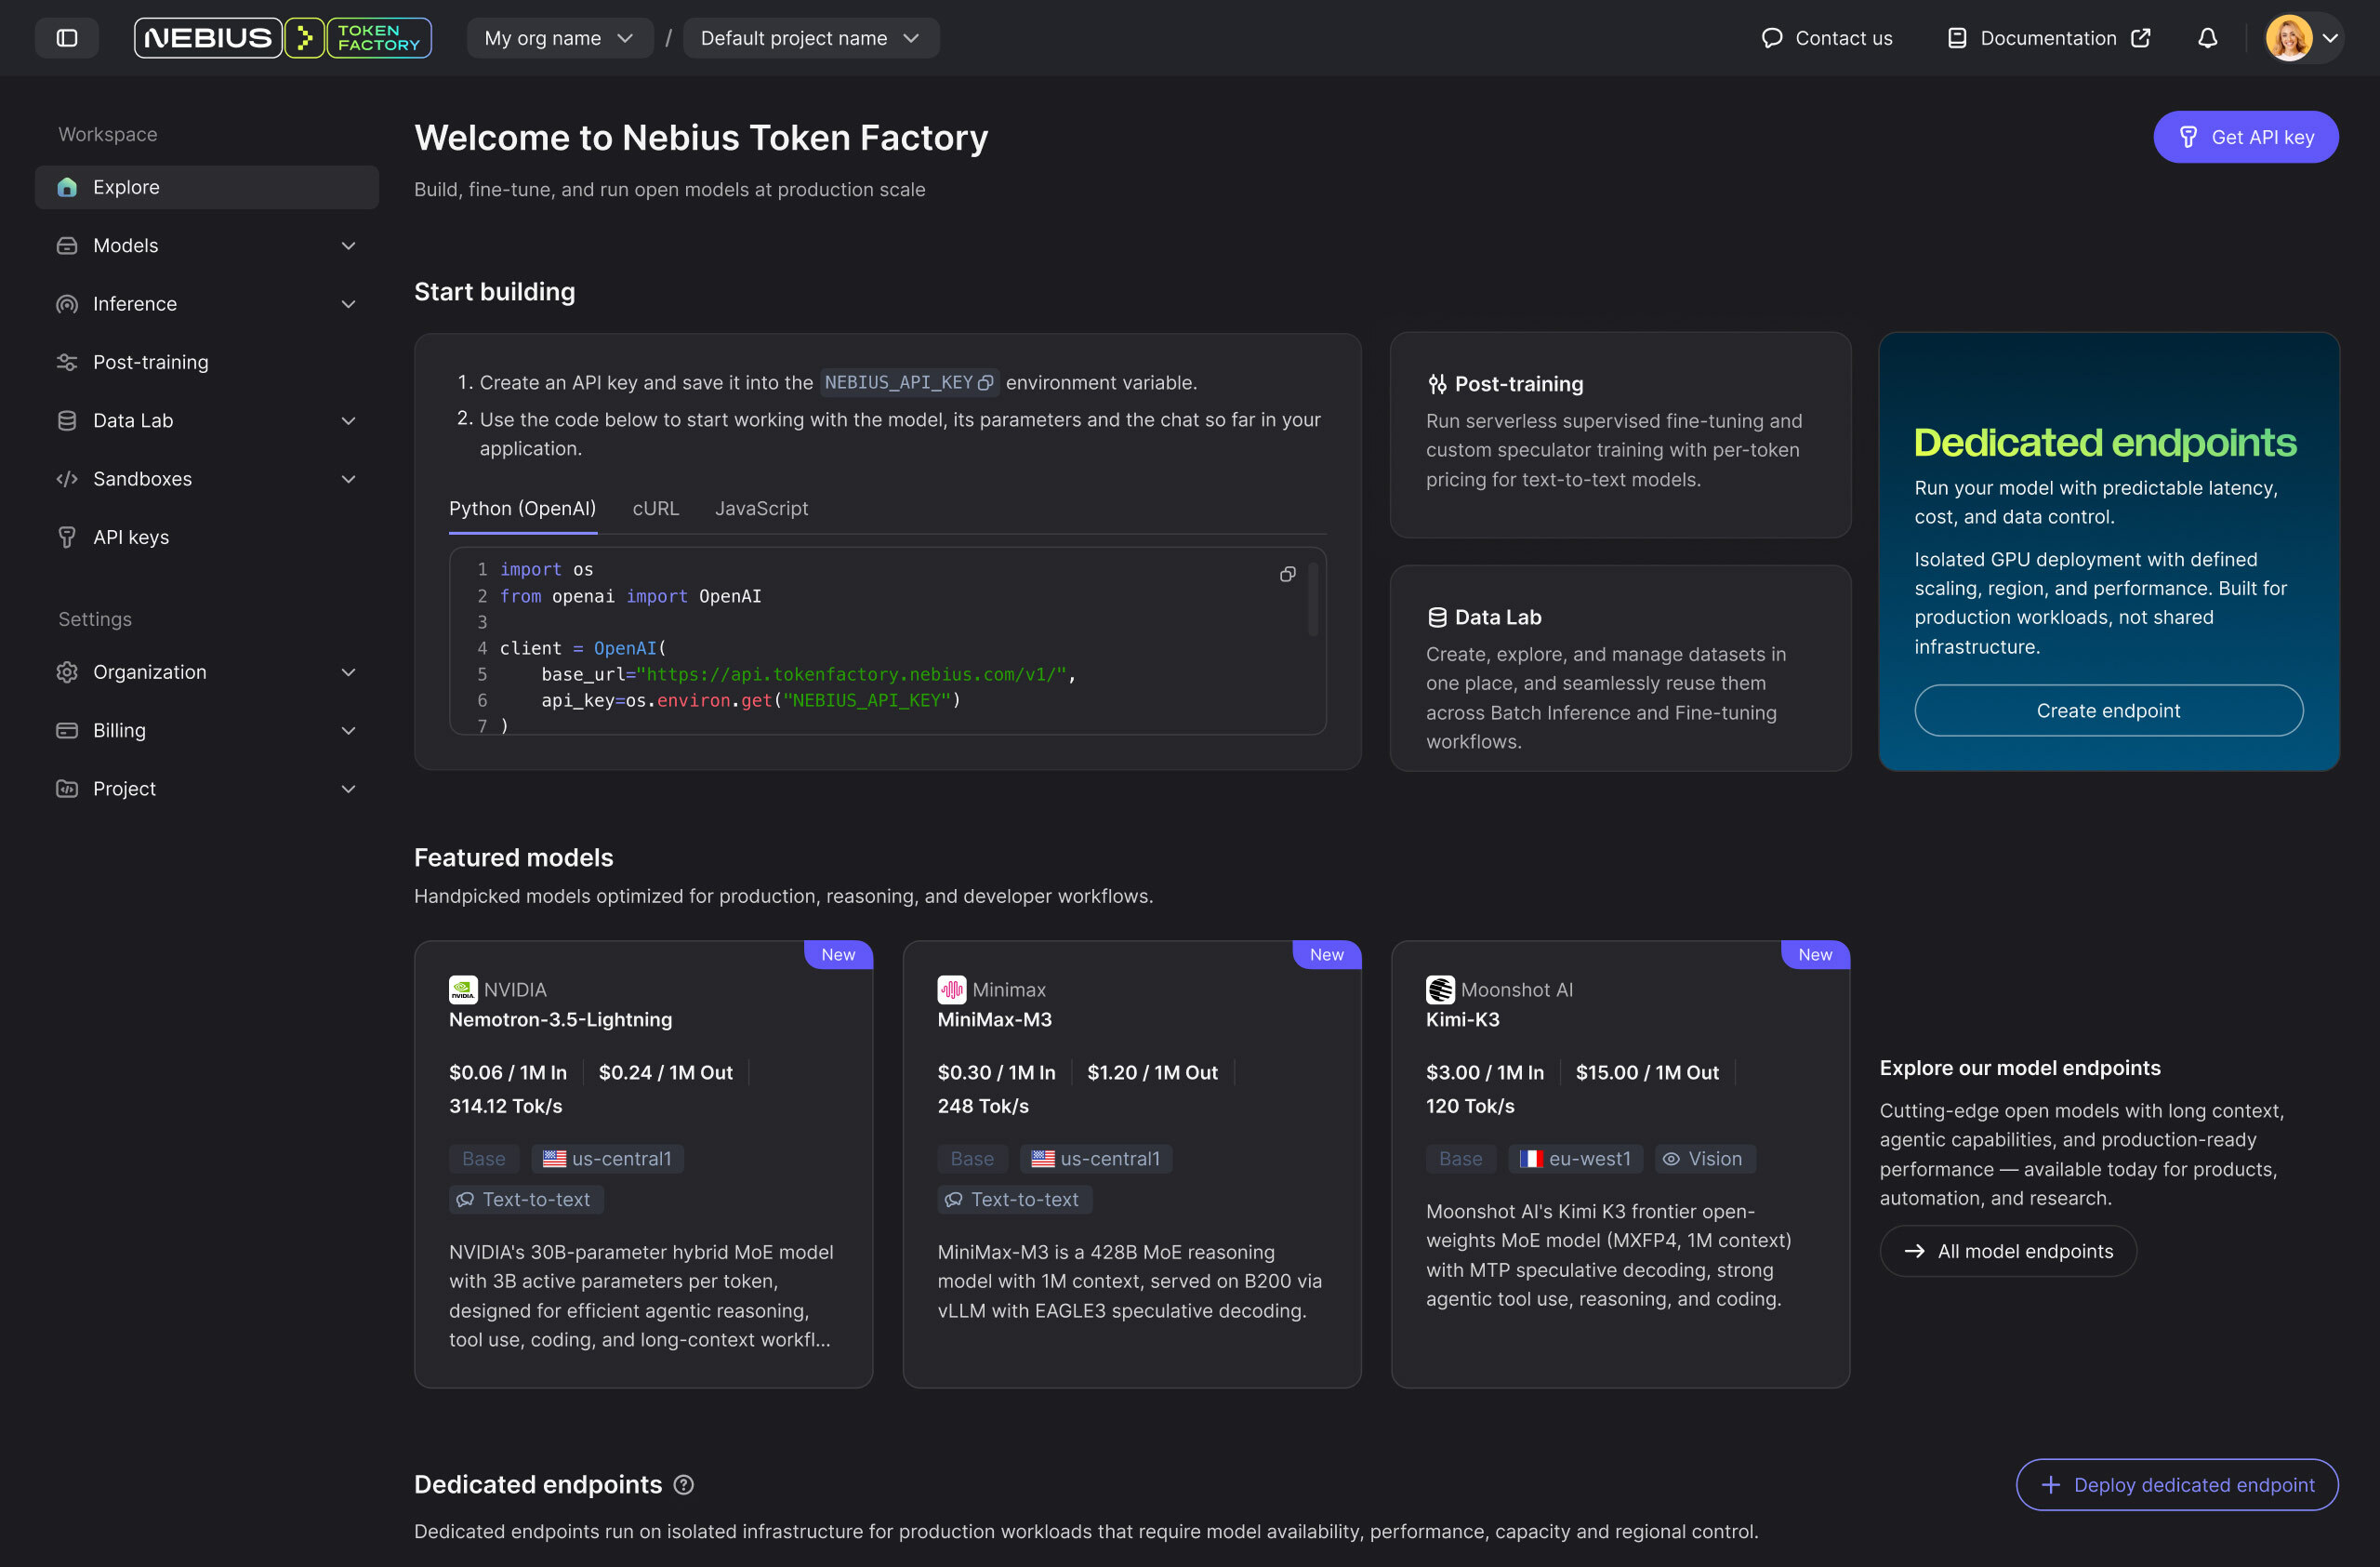
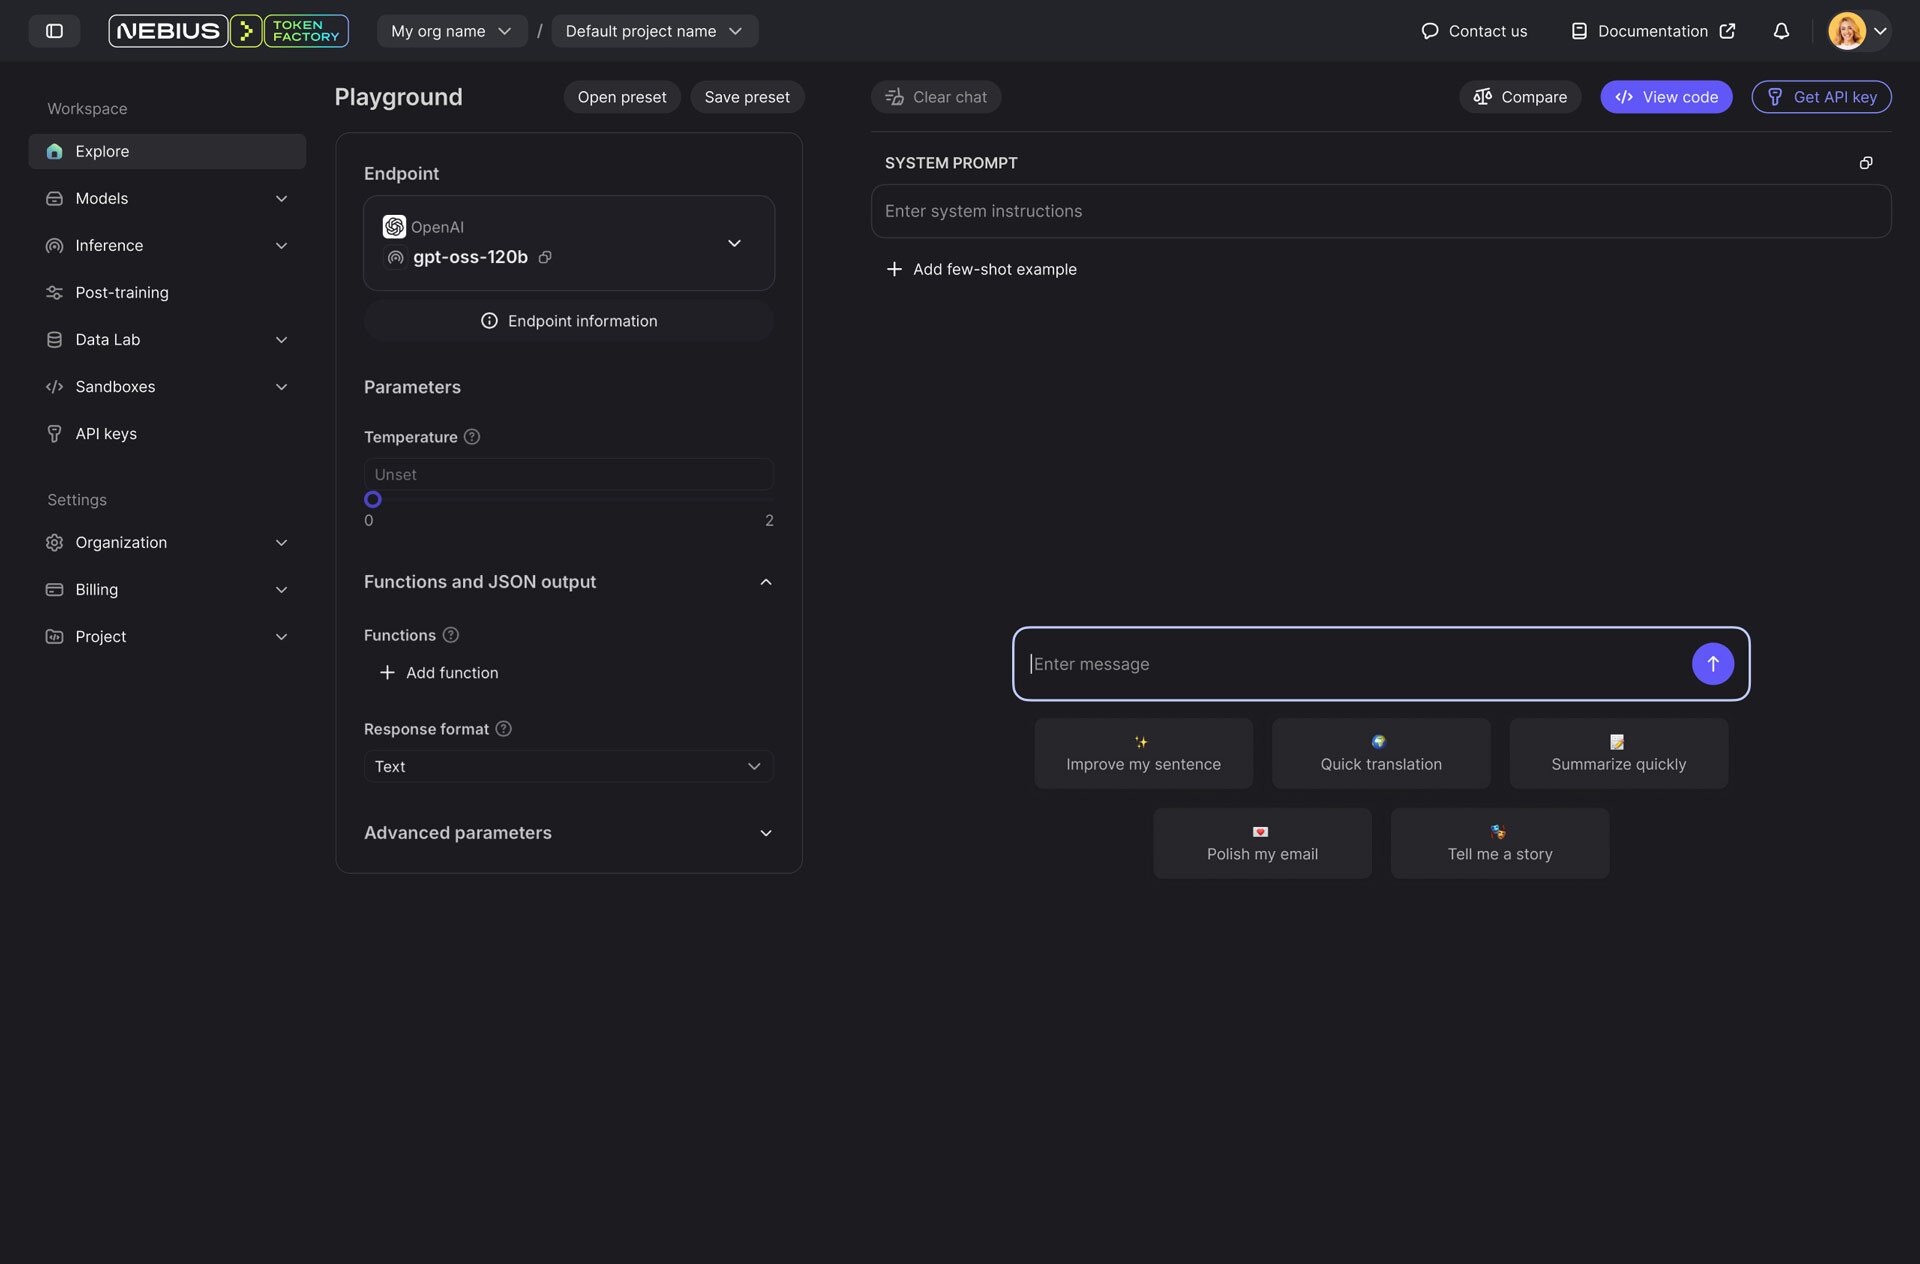
A simple and friendly UI for a smooth user experience
A simple and friendly UI for a smooth user experience
Use the Playground to compare Kimi-K3, Kimi-K2.7-Code, and Kimi-K2.6 on your own agent trajectories, coding tasks, long prompts, tool schemas, and images. Refine prompts and export an API-ready request when you are ready.
Familiar API at your fingertips
Use the OpenAI-compatible API and switch between Kimi models by changing the model ID.
import openai
import os

client = openai.OpenAI(
    api_key=os.environ.get("NEBIUS_API_KEY"),
    base_url='https://api.tokenfactory.nebius.com/'
)

completion = client.chat.completions.create(
    messages=[{
        'role': 'user',
        'content': 'What is the answer to all questions?'
    }],
    model='moonshotai/Kimi-K3'
)
Choose how to run Kimi
Deployment option
Best for
What you get
Public endpoints
Evaluation, prototyping, and variable traffic
Pay-per-token access with no deployment required
Dedicated endpoints
Workloads that need isolated capacity or regional control
Availability is model-specific; confirm the selected Kimi model before committing
Custom deployments
Private weights or specialized requirements
Workload-specific sizing and deployment support
Frequently asked questions
Start with Kimi-K3 for the strongest current long-context, multimodal agent experience. Use Kimi-K2.7-Code for software-engineering agents and Kimi-K2.6 for multimodal research and visual workflows.